

unschooled autodidact interested in inner work / self development / understanding myself and others. technical staff @ https://nitter.cf/t.co/1HqI3jcQqL
San Francisco
Joined September 2019
- Tweets4.9K
- Following356
- Followers1.4K
- Likes10.9K





insanely misleading how they juxtapose a (1) agentic model editing autoresearch result, and (2) manual weight editing with no tool calls for small networks.
steering vectors v.s. compiling algorithms into weights.

oh my god. my entire timeline now is horrible takes on the weight-space programming paper from people who clearly did not even ask a model "what did they do here? are their results overstated or misleading?"
ime viral ml research is surprising before i fully understand what they did. once i understand it’s usually not very surprising
underrated: just give a paper to claude and ask it for a non-overstated review. so many people on the timeline rn don't even do this. you don't even have to be technical! the models are pretty good at this!
for the qwen3.5 "weight editing" result astra is essentially just deriving a steering vector from a bunch of looping/non looping reasoning examples + trial and error. unsurprising! we've known for ages that this kind of thing works


We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: rikiyat.github.io/blog/weigh…

Ulisse Mini retweeted

the only way into believing that only a fraction of humanity is conscious is by being so dissociated that you're unable to truly see them, beyond your thoughts about their lives
You’re unable to view this Post because this account owner limits who can view their Posts. Learn more
maybe psychological work and meditation are both maximally concrete problem solving with different focuses? trauma vs greed/hatred/delusion


for any open source project i immediately profile it based on its programming language. rust is excellent, go is great, js is okay, php is run
kegan 3 is less obvious when the social values are around free thinking and agency. mfw pretending to be kegan 4 is kegan 3 in sf
harder and less sexy and far more important lol. extremes are nice bc they never happen
I used to really relate to Grenade by Bruno Mars, listening to it now i see he has issues (that i also had/have)
love a song -> grow -> see song as evidence of mental illness

weird thing here is that i expect nick would have predicted all these results & it’s mostly talking past each other, different meanings of “understand”, standards of evidence, etc
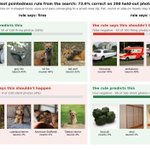
@nickcammarata's essay says InceptionV1 neuron 4e:55 fires on pointed things and not round ones. on the essay's own photos (top), that holds. on other ImageNet photos (bottom), all four combinations happen: round fluffy faces fire, pointy German shepherds stay silent 🧵

me/cfs is horrible! I’ve known adic a long time and it’s been awful to see her life get destroyed from this. i really hope we get large advances in biology soon!


@nickcammarata's essay says InceptionV1 neuron 4e:55 fires on pointed things and not round ones. on the essay's own photos (top), that holds. on other ImageNet photos (bottom), all four combinations happen: round fluffy faces fire, pointy German shepherds stay silent 🧵

interpretability might be the most important scientific problem in the world right now, as I don't think we can solve alignment if we don't know what we're building. I think I have good news about it. I co-authored early work in mechanistic interpretability at OpenAI and came away pessimistic, because neural networks appeared to fold into arbitrary tangled knots. years later, I started openai's first large-scale automated interpretability project, finding about 2% of neurons legible with the primitive tools we had
with modern agentic tools and a much closer look, the picture looks totally different. the vast majority in models up to trillions of parameters are legible, and their circuits beautiful. many famous examples of tangled neurons turned out to be misunderstood. The roadblocks I expected mostly aren't there. I now think ambitious interpretability will be solved by the time we need it most, and possibly quite soon, as automated scientists keep improving. it may be a bitter lesson for interpretability: the simple thing, at absurd scale, works
already-clean.goodfire.com/

to conclude, if there's a crisp pointed vs round distinction here, I can't find it! I'd love to see if nick can predict this neuron better with his understanding now (as opposed to before) or figure out other good sharable "proofs/evidence of understanding"
experimental details and more experiments: ulissemini.github.io/4e55-ga… (got seriously nerdsniped)
there's more i'm curious about, like ideas for leveraging LLMs to their full epistemic potential (infinite smart researchers, blinded however you want!) but that will have to wait. I've spent too long on this already 😅