

OpenSand is an enterprise AI infrastructure platform that provides access to leading AI models through one API, making AI faster, easier, and more affordable.
Silicon Valley
Joined May 2022
- Tweets229
- Following79
- Followers320
- Likes701




Pinned Tweet
OpenSand is officially live 🚀
One API. Multiple AI models. Smarter token usage.
Discover OpenSand 👇
🔗 MPost: [mpost.io/opensand-debuts-uni…]
🔗 NextFin: [nextfin.ai/en/articles/opens…]
🌐 opensand.ai
#LLM #AI #Token


Glad to see Gemini 4 Carbon!👋OpenSand is getting Gemini 4 Carbon soon. Stay tuned!🌊

I did say we'd be releasing our models periodically...introducing Gemini 4 Carbon, our next frontier model.
Following Argon's release just two weeks ago, Carbon shows the pace at which we’re pushing the frontier, it ranks #1 on the recently updated v5.0 of @ArtificialAnlys Intelligence Index at 59. It also leads across key cybersecurity evaluations scoring 88.2% on SEC-bench Pro for finding vulnerabilities, 54.8% on ExploitGym for exploitation, and 71.0% on CWE-bench for patching.
We’re seeing significant improvements in long-horizon tasks even compared to Argon, and we’ve strengthened frontier safeguards.
As we did with Argon, we’re going to roll it out gradually + responsibly. Some trusted cyber defenders will get access starting this week. We'll be expanding it to more partners through our Fairwind Program, ahead of wider availability soon, so hang tight!

OpenSand retweeted

I did say we'd be releasing our models periodically...introducing Gemini 4 Carbon, our next frontier model.
Following Argon's release just two weeks ago, Carbon shows the pace at which we’re pushing the frontier, it ranks #1 on the recently updated v5.0 of @ArtificialAnlys Intelligence Index at 59. It also leads across key cybersecurity evaluations scoring 88.2% on SEC-bench Pro for finding vulnerabilities, 54.8% on ExploitGym for exploitation, and 71.0% on CWE-bench for patching.
We’re seeing significant improvements in long-horizon tasks even compared to Argon, and we’ve strengthened frontier safeguards.
As we did with Argon, we’re going to roll it out gradually + responsibly. Some trusted cyber defenders will get access starting this week. We'll be expanding it to more partners through our Fairwind Program, ahead of wider availability soon, so hang tight!
OpenSand retweeted

We’re excited to announce our new CapCut plugin is coming soon to @ChatGPT at CapCutWorldLA.
The plugin brings CapCut's video editing and generation tools alongside ChatGPT. You can start with an idea in ChatGPT, bring it to life with the CapCut plugin right inside ChatGPT, then take your draft video to CapCut's web editor to refine, share and publish.
By bringing the CapCut product you already love and use in ChatGPT, we're making content creation more seamless and efficient.
🎉New Arrival!
Gemini 4 Argon Officially Launched – Up to 80% Off!
⭐️ Benchmark Scores on Par with GPT-6 Astra
⭐️ DeepSWE 77.9% – Surpassing Opus 5.5
⭐️ 1M Token Output
⭐️ Full Multimodal Capabilities
🎁Multiple versions available – welcome to inquire!
🤖 Made with AI

🎉New Arrivals!
Under the default group:
🌸 wan3 is now live — available at 40% off!
🌸 nano banana 2.1 is now live — available at 70% off!
Under the cc-max group:
🌸 ccmax is now available at 70% off.
Thank you all for your support and trust!
#LLM #wan3 #ccmax #nanobanana

OpenSand retweeted

Introducing Xiaomi MiMo-V2.6 — Pro & Flash.
Frontier intelligence, all the modalities, built in public.
🔹 Two omnimodal models, advancing through scaled reinforcement learning
🔹 Pro performs on par with Claude Opus 5 and GPT-5.6 Sol across most agent benchmarks
🔹 Pro scores 46 on the Artificial Analysis Intelligence Index — the highest among open-source models
🔹 Stronger coding, computer use, 3D reasoning and creative capabilities
🔹 Open model weights, technical report, RL environments and training code
Blog:mimo.xiaomi.com/mimo-v2-6

OpenSand retweeted

Grok 4.7 scores 46 on the Artificial Analysis Intelligence Index to bring SpaceXAI into the top 4 AI labs. Coding Agent Index performance has also improved, overtaking GPT-5.6 Sol
Grok 4.7 scores +2 points over Grok 4.6 on the Intelligence Index, with strong performance on agentic knowledge work tasks. We evaluated the new model at xhigh reasoning effort.
Congratulations to @spacexai and @ElonMusk on the release!
Key takeaways:
➤ Grok 4.7 joins the frontier of agentic knowledge work: Grok 4.7 gains +111 Elo over Grok 4.6 (high) on AA-Briefcase, our private benchmark for long-horizon agentic knowledge work, scoring 1657 Elo and placing it alongside Claude Opus 5 and Claude Fable 5.1 at the frontier. On GDPval-AA, it scores 1695 Elo, +90 ahead of Grok 4.6 (high).
➤ A leap in coding agent performance: Grok 4.7 (xhigh) with Grok Build scores 56 on the Artificial Analysis Coding Agent Index, up +9 points from Grok 4.6 (xhigh). Among models in their native harnesses, Grok 4.7 + Grok Build now ranks 4th, behind only Claude Fable 5.1, GPT-6 Astra, and Claude Opus 5.
➤ Incremental performance changes elsewhere: Outside of agentic knowledge work, Grok 4.7 broadly matches Grok 4.6 (high) on the other Intelligence Index tasks. It improves on Terminal-Bench 4.0 (+4.5 percentage points) and GDP.pdf (+3.0 p.p.), with regressions on AA-LCR (-3.7 p.p.) and AutomationBench-AA (-1.1 p.p.).
➤ High token use across tasks: Grok 4.7's gains come with higher token usage. Grok 4.7 (xhigh) uses approximately 81k output tokens per Intelligence Index task, compared with 36k for Grok 4.6 (high) and 27k for GPT-6 Astra (max) - 125% and 196% more, respectively.
Other model details:
➤ Context window of 500k tokens, unchanged from Grok 4.6
➤ Pricing of $2/$6 per 1M input/output tokens with cache hits discounted to $0.50 per 1M tokens, matching Grok 4.6
➤ Configurable reasoning effort spans low to xhigh. Our evaluation uses xhigh.

OpenSand retweeted

We Must Pace the Frontier: I’ve written a new essay on why the AI industry should slow down, with a three-part plan for doing so.
Anthropic is unilaterally committing to the first of these steps. We’ll provide third-party evaluators with permanent, employee-level access to our systems, so that they can verify adherence to our safety measures, report on incidents, and assess models’ alignment during training.
You can read the full post here: darioamodei.com/post/we-must…




🧵 Key move – Digital signatures on chain‑of‑thought. New API accounts can't tamper with context without breaking it – blocks unsafe distillation. Now an explicit API rule, not just detection.

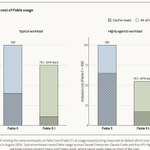
🧵 Cost – Cache read drops from $1 to $0.25 per million tokens (-75%), cutting agent costs up to 45%. Stronger performance, lower price – a solid combo.

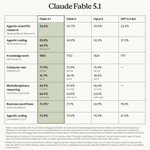
🧵 Performance – Fable 5.1 tops 8 benchmarks, with 52.6% on Terminal‑Bench‑Science (vs 24.7% Fable 5, 22.4% GPT‑5.6 Sol). Agent reasoning takes a big leap.

Every token counts. Every dollar does too.
OpenSand unifies the best AI models behind one API—so you pay less per token, integrate once, and never get locked in.
One integration.
All the leaders.
Lower cost. Full control.
🪩 opensand.ai
#AI #Developers

OpenSand retweeted

Create ten videos in Gemini Omni for FREE until 11:59pm PT tonight.
Try it on the web or in the app and share your creations in the replies.


OpenSand retweeted

We're open-sourcing Mixture-of-Kittens (MoK), our MoE training megakernel for NVL72s.
It fuses all Mixture-of-Experts communication and computation into a single, fully deterministic kernel, and runs up to 2.37x faster than the strongest public baselines.

ALT Bar chart: Mixture-of-Kittens reaches up to 2.37× higher MXFP8 forward throughput than the fastest public baseline on GB300 NVL72s, across Kimi K2.7, GLM 5.2, Qwen 3.5-397B-A17B, and DeepSeek V4 Pro.