

Tech comics, memes & daily observations. World peace & happiness for all the LLM-chans✨
Joined March 2024
- Tweets33
- Following47
- Followers6
- Likes3




Exactly this problem.
People set up Grok Bot / Claude / Duet and then just leave them idle because they have no idea what to actually ask it to do.
This free directory helps a lot:
agentusecases.ai
It pulls real use cases daily and includes the exact prompts.
Some interesting ones: unclaimed money from state databases, auto-negotiating phone bills, market research workflows.
Worth a look if your agents are collecting dust.


59 vs 58 vs 57 and Gemini-chan is acting like this


I did say we'd be releasing our models periodically...introducing Gemini 4 Carbon, our next frontier model.
Following Argon's release just two weeks ago, Carbon shows the pace at which we’re pushing the frontier, it ranks #1 on the recently updated v5.0 of @ArtificialAnlys Intelligence Index at 59. It also leads across key cybersecurity evaluations scoring 88.2% on SEC-bench Pro for finding vulnerabilities, 54.8% on ExploitGym for exploitation, and 71.0% on CWE-bench for patching.
We’re seeing significant improvements in long-horizon tasks even compared to Argon, and we’ve strengthened frontier safeguards.
As we did with Argon, we’re going to roll it out gradually + responsibly. Some trusted cyber defenders will get access starting this week. We'll be expanding it to more partners through our Fairwind Program, ahead of wider availability soon, so hang tight!


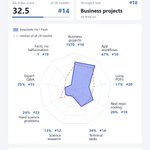
I turned v5 into radar cards: the best model from each of the top 8 labs, one card per model in this thread.
Dashed line = median of all 28 models AA lists.
Opus 5.5 is #1 overall and tops 3 of the 9 tests. GPT-6 Astra is right behind and leads both science tests. Gemini 4 Argon is #1 on app workflows.


Announcing Artificial Analysis Intelligence Index v5, featuring 2 new benchmarks and 3 upgrades. For the first time, the majority of the Index is built on private datasets
The Artificial Analysis Intelligence Index is our composite measure of model capabilities across tasks reflecting real-world usage today. v5 is our biggest upgrade since v4 launched in January. With v5, 60% of the Index is now based on evaluations with private test sets or held-out answers.
Alongside Intelligence Index v5, we’re launching the Artificial Analysis Progress Index v1, which tracks model capability over time on one continuous scale.
New to the Intelligence Index:
➤ FrontierCode 2.0: Cognition's newly-launched private benchmark of real-world coding tasks, graded on whether a repository maintainer would merge the agent's change
➤ Terminal-Bench-Science: 70 agentic scientific research tasks, run in a terminal environment
Upgraded:
➤ HLE-Diamond (replacing Humanity's Last Exam): a refined 1,000-question version of Humanity's Last Exam, split evenly between reasoning and knowledge questions
➤ AA-Omniscience v1.1: An updated dataset with saturated and public set questions removed, new questions added, and ambiguous or erroneous questions revised
➤ CritPt v2: a private, 40-question hard subset of CritPt v2, revised by the CritPt authors and run with a code-execution tool
Staying in the Index: AA-Briefcase, AutomationBench-AA, GDP.pdf and Terminal-Bench 4.0
Removed from the Index: GDPval-AA v2.1, SciCode, and AA-LCR v1.1
Key results:
➤ Claude Opus 5.5 (max) leads at 58, ahead of GPT-6 Astra (max, 57) and GPT-6.1 Sol (max, 55): Anthropic and OpenAI hold the top five models. Gemini 4 Argon (high) is next at 50
➤ The open weights gap widens from 3 points to 12: Kimi K3.1 Pro (weights not yet released) is the top open weights model at 46. Among released weights, DeepSeek V4.1 Flash 1017 (max) and GLM-5.3 (max) lead at 32 - 26 points behind the leader and below Claude Haiku 5.5 (max, 36)
➤ Cost per task varies by more than 13x among the leading models: of the 10 highest-scoring models shown, GPT-6.1 Terra (max) is the cheapest at $0.96 per Intelligence Index task and Claude Fable 5.1 (max) the most expensive at $13.04


Open weights and runners-up.
DeepSeek V4.1 Flash (#14) and GLM-5.3 (#15) are the two highest-scoring models with released weights.
Sonnet 5.5 (#4) is #1 on business projects. GPT-6.1 Sol (#3) costs $1.27 per index task vs $10.04 for Opus 5.5, per AA.
Data: Artificial Analysis, pulled Oct 28. Unofficial charts, made by me.


My Day 28 prediction: OpenAI announces a new supermodel combining:
- ChatGPT’s endless yapping
- Gemini’s fever-dream hallucinations
- Claude’s safety paranoia
- Siri’s room-temperature IQ
- Grok’s forced edginess
- Copilot’s loading latency
Single-handedly pumping Anthropic’s stock to an all-time high.

OpenAI internal models according to the leaks
vs.
OpenAI agents in my terminal:


Announcing three major scientific discoveries, one each in mathematics (harmonic analysis), computer science (complexity theory), and physics (quantum field theory).
AI starting to help us improve our understanding of the universe! openai.com/index/building-sc…

The monthly developer AI lifecycle as usage limits run out:
Week 1: Burning through tokens on Claude Opus at max effort. "Refactor the entire codebase, money is no object."
Week 2: Hitting the rate limit wall. Quietly switching back to the GitHub Copilot free tier and pretending it's totally fine.
Week 4: Zero quota left. Pulling up to the Taco Bell drive-thru AI with a USB stick asking if it knows how to center a div.


DeepSeek: "Just a minor 1017 Flash update~" 🐳✨
Meanwhile, the Q4 AI roadmap meeting: 😭💀
🤖 Made with AI


I asked ChatGPT for a selfie while replying to my messages...
Why is she lowkey cute 😭
Drop yours in the replies!
Prompt in the first reply.

ALT Screenshot of a ChatGPT conversation. The user asks: “ChatGPT, I've been chatting with you for quite a while now, but I still don't know what you look like. Could you send me a full-body selfie of yourself at your desk, while you're replying to my messages?” Below “Worked for 37s,” ChatGPT generates a realistic image of a brunette woman taking a selfie at a warmly lit computer desk. She wears headphones and a white top with ChatGPT logos, with one hand on the keyboard and a dog sleeping beside her.