
Working on AI gov. Past: Technology and Security Policy @ RAND re: AI compute; telemetry database lead & 1st stage landing software @ SpaceX; AWS; Google.
Cambridge, MA
Joined November 2010
- Tweets7.6K
- Following3.6K
- Followers1.4K
- Likes46.4K
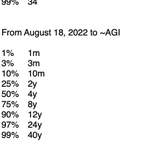


The AI safety community seems to have updated massively on relatively little incremental evidence, largely as a result of a reputation-based opinion cascade.
This might just be noise but we shouldn’t be surprised if it’s not noise. All of this depends so much on your task suite. It’s analytically very convenient to pretend that’s not the case. But sadly it is the case.


David Schneider-Joseph 🔍 retweeted
In particular, it’s entirely possible to have gotten *no better at all* at AI R&D, even with more spending, compute, coding AIs, etc. and for the ECI to curve upwards over time.
I don’t *believe* that this happened, but our tools for saying it didn’t are very limited.

Completely insane to deny students access to AI.

NYC has a moratorium on student facing AI for K through 8th grade.
Google says we are going to force you to break your own rules, you can't have search without AI.
NYC must call Google's bluff, kick out search, and refer the case to the AG and DA for illegal tying and abuse of monopoly power.
The idea that any other Ed Tech company could say "you only get the tool you want if you break your own policies" would be nonsense.
David Schneider-Joseph 🔍 retweeted

An incredibly confusing but apparently true fact is that James Talarico’s chief of staff is named Gina Hinojosa.

The funniest possible outcome in Alaska would be if the fake Dan Sullivan wins because everyone puts him as their second choice
1
5
220

David Schneider-Joseph 🔍 retweeted

turns out it classifies what audio it hears, before reporting back to samsung.
sensor preferences, dog-barking and baby-crying event counters, and camera streaming duration are built into telemetry paths.


David Schneider-Joseph 🔍 retweeted

Ok, I just checked this, and its literally running a freaking TensorFlow Lite model on 960×540 images with INT8 quantization every couple of seconds in an attempt to figure out what game you are playing.
It's literally called "alex.tflite" and its literally AlexNet and seems to follow torchvision.models.alexnet. As far as I can tell this does some strange nearest neighbor feature comparisons against a DB and literally doesn't work 99% of the time, you love to see your CPU get wasted every other second by this thing though. It also just seems to dump its results into the void because the consent gate comes later.
Anyways, here's the tf model graph and some dumped captures.


live-tweeting on samsung findings were fun.
i'll let my agents give it a bit more time, but this document is already the most comprehensive breakdown of some key concerns of tizen i've seen run on a live device.
it takes like a good while for me just to scroll through it (there's about 44 writeups as of right now on individual functionality).
release is probably happening in a few days.

This may be one of the most important uses of abliterated models: helping people escape from technofeudalism.

Samsung TVs look for microphones in your house via Bluetooth and then spy events like dogs barking or babies crying. They also spy what you do on YouTube and other apps.
Thanks abliterated DeepSeek.
7
336
But you can be a capabilities believer and think the average "safety" plan makes things less safe, by giving unchecked power to authoritarians over a dangerous technology.

imo you can be a capability skeptic and not be a safety skeptic but you can't be a safety skeptic without being a capability skeptic
217
David Schneider-Joseph 🔍 retweeted

Important, and I'm glad this is finally public. Google DeepMind researchers are under in perpetuity non-disparagement clauses forbidding them from ever speaking critically of the company. I'd already confirmed this with multiple people.
Yes, some ex-employees have spoken out nonetheless. But it has also discouraged others from doing so. And yes, it most certainly has a chilling effect with regards to discussions on safety and risk.
Others have written compellingly about how important the ability to speak freely and critically is, especially on topics like safety and risk. And what a testament to the research employee community's coordination and hard-won bargaining power it has been to get there at other companies.
GDM burn that commons by having this. And everyone who signs burns that commons too. Let's get it changed.

Congrats to Sofia for having the courage to resign and speak out!
This is also very important:
Staff are scared to speak out about AI safety and its uses in warfare because their employment contracts prohibit them from publicly criticising the company.
bbc.co.uk/news/articles/cmre…

David Schneider-Joseph 🔍 retweeted

Lots of ppl have criticised Anthropic's bill for making it too hard for the govt to shut them down
This thread defends Anthropic: routing shutdown through the courts is needed to avoid extreme power concentration.
Idk how to strike the tradeoff.
I do wish AI safety spent more time asking "what would happen if the executive abused my proposal to take control of AI development"

Whatever happens with looped models or whatever in the future, chain of thought monitoring has already paid enormous dividends in AI alignment research and it's worth reflecting on that, given how skeptical people were of its value like two years ago.
7
344
David Schneider-Joseph 🔍 retweeted

This obviously makes it so that when OpenAI announces they're conducting an external investigation with regulators or auditors, everyone working with those regulators and auditors understands they'll be fired if the auditors or regulators learn too much.
Damn and I was just giving OpenAI some credit like three days ago.

OpenAI fired me last week, along with two of my safety colleagues. I was given one reason: that I accessed an executive's email. I want to say this plainly, because too many of OpenAI’s history is smoke and mirrors when people disappear:
12
335
*has only a single mechanism
(There are multiple mechanisms for the other direction, some listed in the article.)
37