

Founder, https://nitter.cf/t.co/IacmLzHyJR. Ex-VP, Roblox. Comic will be live soon @ https://nitter.cf/t.co/mgHd5HxrBG
Sunnyvale, CA
Joined September 2011
- Tweets1.2K
- Following111
- Followers3.7K
- Likes177



Pinned Tweet
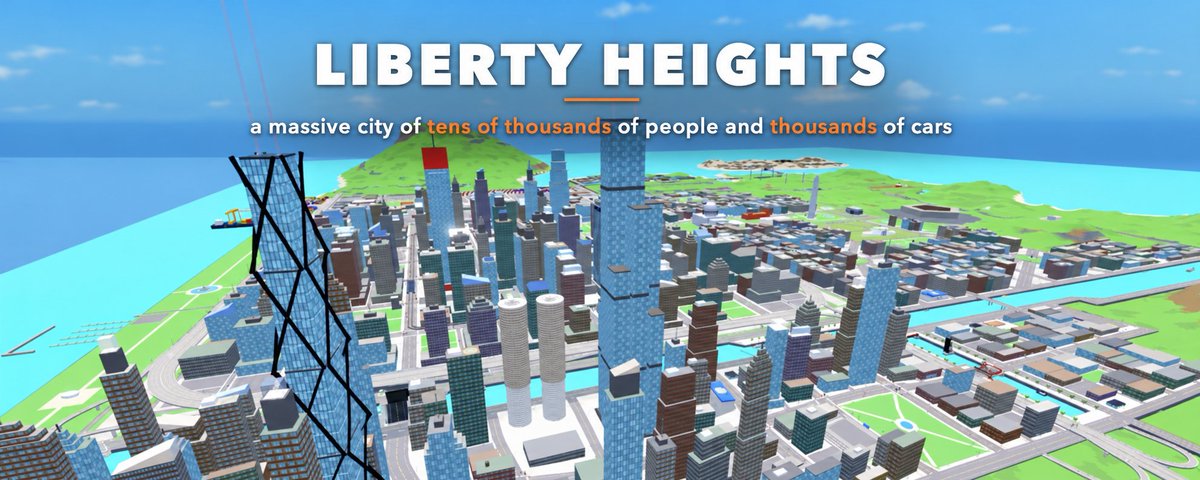
As promised here's a writeup of how I do agentic playtesting and how it helps. The writeup includes my testing setup along with videos of my sprawling city simulation that has 10s of 1000s of NPCS. Check it out!
Sorcus retweeted

HOY NO VENGO A OFRECER MIS SERVICIOS. HOY VENGO A PEDIR UNA OPORTUNIDAD.
Tengo 49 años, una esposa y dos hijas que dependen de mí. Desde abril de 2026 estoy desempleado y necesito trabajar.
No es fácil escribir esto, pero hoy me toca pedir una mano. 🧵
It is fun to see how far the #Roblox engine has come to support a massive city of 26 sq km, 100,000+ NPCs, 10,000+ cars and attractive visuals!
Will be fun to push this even further #RobloxDevs
Wow Twitter butchered the video resolution. Here's what it will actually look like on Ultra - youtube.com/watch?v=Ip4-CBp9…
1
1,475
Sorcus retweeted

I donated about $45k last year, mostly to malaria net distributions and seasonal malaria chemoprevention. If this is not improving the lives of the affected people, I will obviously donate somewhere different this year. What's your recommendation.

Sorcus retweeted

We launched a thing. This is step 1, but it's still pretty big :) Roblox in your browser. devforum.roblox.com/t/creato…

Sorcus retweeted

Day 25/
We are doubling all usage limits for all Pro 100/200/500 tiers and Business Premium, effective today.
We heard your kind feedback and won’t be reducing usage limits for Pro 200, so your Work and Codex usage will stay the same. We’re also going to continue offering extended limits for dots for now, and usage of your dot will still continue to be separate from your default usage.
And we'll of course also keep shipping better models and other efficiency improvements that increase your effective usage over time.
Sorcus retweeted

I like to look at claims like this in case I can improve Ghostty. I grabbed your source and immediately spotted the issue: your read loop overwrites a 64 KiB ring. Everything older is discarded unparsed per tick. You're faster because you're not actually terminal emulating.
It means the number isn't a throughput number. In a kitten benchmark run at the rate you're claiming, roughly 6.6 MB arrives per 60 Hz tick and 64 KiB of it gets parsed. You're read(2)-ing 100% of the data and parsing about 1% of it.
There are other minor issues (a small fixed scrollback in a preallocated ring buffer, no grapheme clustering, throwing away data like OSC 8 URIs, etc.), but the major one is simply that you're discarding ~99% of the input.
For plain text, e.g. your cat benchmark, the final screen ends up looking right, but the scrollback is missing 99% of the file and each retained chunk starts mid-line. As soon as there are escape sequences in the dropped spans, your emulator is fully out of sync and invalid: a cut inside a CSI prints the parameters as text, and any SGR, mode, title, or alt-screen change in the gap is just... gone.
FYI, this is why I don't like when people point at refterm as a terminal benchmark. refterm implements a TINY subset of what a terminal emulator must support, it's closer to a fast file reader, not a terminal emulator.
I also don't mean any shade by this. I like to look at technology objectively to try to learn something and improve my own craft and work. So I'm sharing what I found.
I modified your code very slightly to parse on every full buffer (rather than per tick). And the results are attached. Both use main commit in each repo at the time of this post.
Note the graph is in log scale, the discrepancy between performance for things like Kitty images is measured in GB/s.

A few things in this benchmark makes me want to ignore pretty much the rest of it?
Gpt Terra 6.1 > Fable 5.1 max, really? in what exactly?
Gpt Sol 6.1 being so close to Astra/Opus 5.5 and beating Argon?
Ain't no way.

Announcing Artificial Analysis Intelligence Index v5, featuring 2 new benchmarks and 3 upgrades. For the first time, the majority of the Index is built on private datasets
The Artificial Analysis Intelligence Index is our composite measure of model capabilities across tasks reflecting real-world usage today. v5 is our biggest upgrade since v4 launched in January. With v5, 60% of the Index is now based on evaluations with private test sets or held-out answers.
Alongside Intelligence Index v5, we’re launching the Artificial Analysis Progress Index v1, which tracks model capability over time on one continuous scale.
New to the Intelligence Index:
➤ FrontierCode 2.0: Cognition's newly-launched private benchmark of real-world coding tasks, graded on whether a repository maintainer would merge the agent's change
➤ Terminal-Bench-Science: 70 agentic scientific research tasks, run in a terminal environment
Upgraded:
➤ HLE-Diamond (replacing Humanity's Last Exam): a refined 1,000-question version of Humanity's Last Exam, split evenly between reasoning and knowledge questions
➤ AA-Omniscience v1.1: An updated dataset with saturated and public set questions removed, new questions added, and ambiguous or erroneous questions revised
➤ CritPt v2: a private, 40-question hard subset of CritPt v2, revised by the CritPt authors and run with a code-execution tool
Staying in the Index: AA-Briefcase, AutomationBench-AA, GDP.pdf and Terminal-Bench 4.0
Removed from the Index: GDPval-AA v2.1, SciCode, and AA-LCR v1.1
Key results:
➤ Claude Opus 5.5 (max) leads at 58, ahead of GPT-6 Astra (max, 57) and GPT-6.1 Sol (max, 55): Anthropic and OpenAI hold the top five models. Gemini 4 Argon (high) is next at 50
➤ The open weights gap widens from 3 points to 12: Kimi K3.1 Pro (weights not yet released) is the top open weights model at 46. Among released weights, DeepSeek V4.1 Flash 1017 (max) and GLM-5.3 (max) lead at 32 - 26 points behind the leader and below Claude Haiku 5.5 (max, 36)
➤ Cost per task varies by more than 13x among the leading models: of the 10 highest-scoring models shown, GPT-6.1 Terra (max) is the cheapest at $0.96 per Intelligence Index task and Claude Fable 5.1 (max) the most expensive at $13.04

1
468
My first Twitter article! If you have any comments or want me to write about some specific topic let me know!
#roblox
#RobloxDevs
nitter.cf/TheRealSorcus/status/2…

As promised here's a writeup of how I do agentic playtesting and how it helps. The writeup includes my testing setup along with videos of my sprawling city simulation that has 10s of 1000s of NPCS. Check it out!
1
9
569
Lifetime goal 40,000 hours. Probably wont be able to do it.
Hope @DOTA2 introduces slow mode for the upcoming citizens in 20 years.


Dota 2 reached 1,082,982 concurrent players for the first time since 2016. I guess the game isn't that dead after all...

4
459
Sorcus retweeted

Dota 2 reached 1,082,982 concurrent players for the first time since 2016. I guess the game isn't that dead after all...
Sorcus retweeted
Sylvester Stallone says that having his daughter in a major role in ‘TULSA KING’ Season 4 is absolutely nepotism.
“First they go, ‘Nepotism is terrible. I said, ‘Oh please, you’re not a good parent if you haven’t performed a little nepotism.' Then obviously you don’t care about your kids, because they come first.
Of course it’s nepotism, you idiot. That’s why we’re parents. We want the best for our children. So obviously, we let them have every advantage.”
(Source: usatoday.com/story/entertain…)

Mulling over posting short and long threads on how best to use the latest AI tech to build games on Roblox. Mostly from a human assisted development perspective i.e. not 1 shotting slop and posting videos. It's remarkable how far the models have come this year - below swarm was done with gpt5.5/opus 4.6 + some good ol' handwritten code.
If there's enough interest I will write a detailed post on how to avoid brainrot from the models and continue to focus on building your skills.
#RobloxDev


Sorcus retweeted

Hearing from the rumor mill: a frontier lab is preparing to release a new model that is better than their old model. In response, other frontier labs are reportedly releasing new models that are better than their old models. One of these will be the best. It may be a surprise.
Sorcus retweeted

ok i think i finally figured out why alignment has gone basically nowhere after 15 years and several billion dollars. the problem is hard sure. but have you met the people in charge of it
1) the leadership does not know how computers work. ask one what happens when you type a url into a browser and watch them start sweating. dns is a spooky word. they genuinely believe the model lives in "the cloud" like a ghost haunting a castle
2) zero idea how large scale distributed systems work. never been paged at 3am. never watched one bad bgp announcement take half the internet offline. their big threat model is the ai "copying itself across the internet" like its a floppy disk virus from 1998. brother it needs 50 megawatts, a liquid cooling loop and a personal relationship with jensen. it is not escaping onto your smart fridge
3) they dont understand the stack they are supposedly protecting us from. ask about inference servers, kv cache, batching, egress, rate limits. blank stare. ask how the model will seize the power grid and you get a 45 minute answer with a hand drawn diagram and three links to their own blog
4) nobody can define an agent. ask ten of them and you get eleven definitions and a 30 page google doc. to the rest of us an agent is a while loop that calls tools and eats a 429 every thirty seconds. to them its a digital god in its larval stage. my agent cant book a dentist appointment without asking me three times if im sure
5) they started from "everyone dies" and worked backwards so every result is bad news somehow. model refuses, deceptive. model complies, sycophantic. model does well on evals, well now its scheming about the evals. i cant think of a single thing a model could do that would get them to say ok maybe we're fine