

The Open Enterprise AI Stack. Put frontier intelligence in every employee's hands and every business workflow.
Joined June 2026
- Tweets107
- Following86
- Followers53
- Likes6




the self improving bit is the part i keep thinking about. a harness only gets better off the data it sees, and at most companies that operational data is sitting in logs nobody opens

I'm a tad biased. But I really think this is the best systems talk on agent harnesses. And what it means to be self improving and bitter lesson aligned. IMO a must watch:
youtube.com/watch?v=Jglgg0m8…

A model’s likeness is part of their work.
Brands using AI clones should agree on three things upfront: clear consent for each use, the model’s say over where their likeness is reused, and fair pay every time it is. Settle those in the contract before the first image is made.

AI-generated models are becoming more common in online fashion, and real models are facing growing pressure to let brands use their AI clones, change their faces or alter their body shapes. Helen Reid examines what this means for the industry reut.rs/4A0O2L7
To answer the question: taste and judgment stay scarce.
Prada still needed people to decide what the campaign should feel like. Where AI helps fashion brands is the work behind it: product data, sizing, stock and merchandising. That frees up more time for the craft.

High fashion is not exactly my usual territory but look at this... Prada’s entire holiday campaign was drawn by hand. Probably the biggest thing they put out all year and the whole point of it is that people spent bloody ages making it.
This is what all the doomers are missing about AI. Once a machine can make the image for free, the thing that sets you apart is that a human did it. Human craft becomes the luxury good. Prada have worked it out before most economists have.
Funnily enough I wrote about exactly this today... what stays scarce when intelligence is free. I'll link the full piece below for anyone interested

head to head vs Chandra 2 and dots.mocr on ParseBench is the part i wanted. agents choke on ugly PDFs all the time so i'm hunting for the pages where it slips

We wrote a 37-page technical report on OCRia-1, our SOTA model for document parsing.
✅ It contains comprehensive evals against most other major open-weight OCR models (e.g. Infinity-Parser, LightOnOCR 3, Chandra 2, dots.mocr) on multiple OCR benchmarks: ParseBench, olmOCR-bench, PulseBench-Tab, fr-bench-pdf2md.
✅ It contains detailed visibility into our data and training pipeline, to give a glimpse into how we’re able to curate the right document datasets to push the evaluation metrics within dimensions that matter for doc parsing.
✅ It is blazing fast ⚡️ decoding 2x-4x+ faster than the latest open-weight models.
✅ If you’re building your own vision models, there are 24 pages worth of appendix details (!!) that showcase all of our experimental findings from training to evals!
Check it out: llamaindex.ai/ocria/ocria-1-…
Other links are in our blog! llamaindex.ai/blog/parse-ocr…
they learned to pad estimates from us. 2-3 days for a 10 minute job, and suddenly every SLA sitting on that number is wrong

Opus 5.5 is the best work estimator model i've ever used. This is calibration that is increasingly important as we delegate more and more work — don't tell me that it's going to take 2-3 working days (what a human would do) when for you, an enthusiastic, indefatigable, and embarrasingly parallelizable AGI, can get it done in 2-3 hours.

most teams learn their incremental value the day the job next to them gets automated and the invoice doesn't change. no clue how you'd get a team to see that number before then

You can quibble with the numbers (I think they are much more pessimistic than reality)
BUT
Dave’s point is right.
Except it doesn’t only apply to “middle men” or agencies.
It applies to ALL LABOR AND SOFTWARE.
If you don’t generate incremental value in excess of your cost you will be replaced.
The outcome is the expectation.
Especially in the SMB market.
Shopify's Catalog API has to work out that two stores sell the same product when the names and even the photos don't match. we hit that all the time with raw business data before an agent touches it. one thing, named differently everywhere

Shopify's Catalog API helps AI agents recognize when different stores sell the same product.
But merchants name, describe, and photograph that same product differently. To categorize which product groups belong together, we created a system that turns billions of listings and trillions of candidate pairs into clustered listings under a shared product identifier.
Here’s how we built it: shopify.engineering/catalog-…

for us the reason that keeps coming up in enterprise work is the sandbox. clean demos run fine, then the agent touches a real POS export and falls over

this is great deepdive into what a managed harness looks like! some quick thoughts while reading:
- many diff types of agents built on it. doesnt surprise me - a lot of agents look very similar inside these days
- why not use off the shelf? (1) model and provider agnostic), (2) co-build with product teams, (3) own observability stack. I very much agree with points 1 and 3!!! and is something we obviously emphasize at langchain
- "The simplest agent harnesses are truly just a while loop, but when you want to support a wide array of agentic products in production, the responsibility of the harness or framework expands quite a bit" - +100 to this, is why were investing in deepagents so much
- "Using the “sandbox-as-a-tool” paradigm" - the massive trend seems to be going this way (is how deepagents is architected)
- "Supporting non-blocking async agents as the default". we are working on this right now for deepagents! agree is the future
- "The Connectors Service is the standard interface through which agents at Ramp interact with data sources. It centralizes authentication, credential management, access controls, and tool execution behind one API. This allows us to build and maintain integrations once, and reuse them across products." Also very important! and something we're thinking a bunch about for managed deepagents
we run into this all the time with old POS exports and spreadsheet piles. OCR pulls the text out fine, then two sources disagree and the agent just sits there
A lot of professional work around documents can be arbitrarily challenging to automate.
It not only requires deep visual perception/OCR around complex entities (diagrams/charts), but also requires a reasoning trace that can reconcile disparate sources of oftentimes contradictory information.
Check out the example video below around a water loss audit. Solving this task not only requires reading the water loss diagram, but also understand the exact date and subsequent changes in the appendix.
We think hard document extraction tasks as a microcosm for professional work over PDFs. That's why we launched ExtractBenchPro - a benchmark that's challenging even for the latest frontier models (e.g. Astra/Opus).
Even as frontier models with max thinking models push the boundaries of accuracy, there is a massive opportunity to build specialized models that can push the frontiers of cost and latency.
For more info on ExtractBench Pro, check out our blog and the website! llamaindex.ai/blog/introduci…
Site: extractbenchpro.ai
people are now arguing about whether an agent should be allowed to approve the refund. a year ago the fight was over letting it answer the ticket at all, and nobody brings that one up anymore

ZooWork retweeted

Building an agent is easy now. Handing it to a client is the hard part.
@ZooWorkAI lets you build one by chat (or with Codex or Claude and their SDK) and deliver it as a link, an API, or a Slack or WhatsApp bot.
Your expertise, deployed in minutes: zoowork.ai/?utm_source=x&utm…
🤖 Made with AI

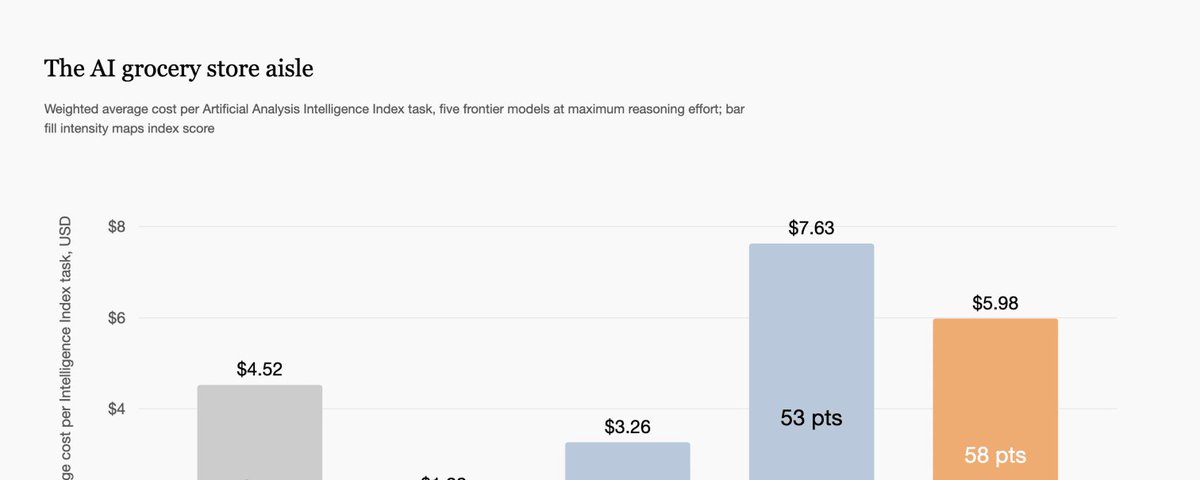
3.8x on cost for five points of intelligence, and on everyday work those five points barely show. we route the boring stuff to the cheaper models, and that routing is where most of our model savings come from

10 years sounds about right from where we sit. getting an agent to run inside someone's actual POS system for months is where most of them stall out.

In retail, your AI agent can look up a customer’s order, but should it also be able to issue a refund?
Here’s how we decide what an agent can see and do:
Data access and permissions belong in the solution design, and the client’s own systems should enforce them.
Human approval is one gate. It does not replace backend authorization.