

Building Hong Kong × China AI Operator Community AI Agents | Workflows | Growth Mindset
Hong Kong
Joined November 2018
- Tweets3.3K
- Following1.1K
- Followers8.9K
- Likes2.5K




Claude Code /artifact-diagramming: 1 skill that teaches Claude to draw better diagrams
→ Step 1: type /artifact-diagramming before you ask for a diagram in an artifact
→ Step 2: Claude loads guidance on when a diagram helps and what to draw
→ Step 3: it also covers writing inline SVG that stays legible in light and dark themes
I think the light-and-dark rule is the detail that saves a re-roll. Needs v2.1.221 or later.
What would you ask it to diagram first?
via @ClaudeDevs code.claude.com/docs/en/comm…

4
2
88
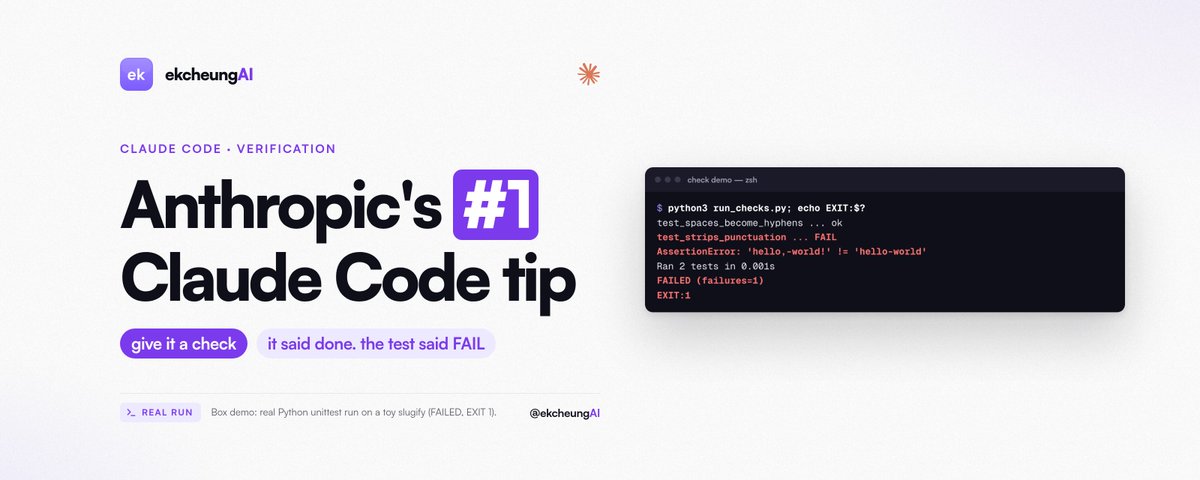
Anthropic's Claude Code team ranks one tip above all the others: give the model a check it can run.
Without one, "looks done" is all it has. The setup, from prompt to Stop hook, is in the article.
11
6
376
Fable 5.2 turned a single prompt into an Honor of Kings-style web game in one night — three years vs one night — and refused to copy the original art over copyright, according to a post showing the build.
Great demo. The receipt is whether it plays past level one.


1
84
Minimax H3's image model generates tens of millions of pixels in one shot and crushes QWEN, according to a post; the post also says some models are uncensored.
Resolution is a spec, not a receipt — show the actual full-res file, not a downscaled screenshot.

1
256
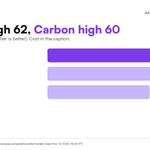
Fable 5.2 high beats Carbon high by 2 points, and is 10.3 min faster
→ Fable 5.2 high: 62 at $9.08, 16.8 min a task
→ Gemini 4 Carbon high: 60 at $7.76, 27.1 min a task
→ Claude Opus 5.5 max: 59 at $10.04, 25.2 min a task
I think the 10.3 minute gap is why I'd pay the extra $1.32 for Fable high.
Is 2 Index points and the time save worth that bill?
via @ArtificialAnlys artificialanalysis.ai/leader…

1
82
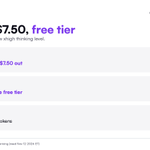
Hydrogen is GA on the free tier, at $1.50 / $7.50 per 1M tokens
→ New model: gemini-4-hydrogen, with a unified 1M-token context window
→ Paid standard price is $1.50 per 1M input tokens and $7.50 per 1M output tokens
→ It adds a 4th thinking level, xhigh, next to low, medium, and default high
I think this is the one to try for everyday coding before you spend Carbon quota.
Would you start on the free tier, or go straight to paid?
via @GoogleAIStudio blog.google/innovation-and-a…

1
107
16 experienced developers took 19% longer with AI tools. Afterward they guessed AI made them 20% faster.
Feeling faster isn't being faster. How to find your own edge, in the article.

AI made experienced developers 19% slower. They thought it made them 20% faster
Article · @ekcheungAI 4
2
180


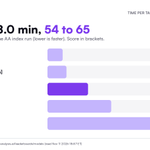
Claude Fable 5.2 max takes 48.0 minutes a task, 2.9x high, for 3 more points
→ Low 54 in 6.2 min; medium 56 in 7.8 min
→ High 62 in 16.7 min; xhigh 62 in 26.3 min
→ Max 65 in 48.0 min at $26.54 a task
I think max is an overnight setting: high gives you 62 while you wait.
How long will you wait for 1 answer?
via @ArtificialAnlys artificialanalysis.ai/leader…

3
92
Gemini 4 Carbon matches Fable 5.2 on Perplexity's WANDR at 40% of the cost
→ Carbon scores 0.857 on WANDR at $5.86 per task
→ Perplexity says that matches Fable 5.2 at 40% of the cost
→ It is now in Perplexity Computer for Pro and Max, and in Search for Max
I think price is Carbon's real pitch: the same WANDR score for 40% of the bill.
Would you swap Fable for Carbon on research jobs?
via @perplexity_ai


Gemini 4 Carbon is now available in Perplexity Computer for Pro and Max subscribers, and in Search for Max subscribers.
It scores 0.857 on our WANDR benchmark at $5.86 per task, matching Claude Fable 5.2 at 40% of the cost.

ALT WANDR score versus cost per task. Gemini 4 Carbon scores 0.857 at $5.86 per task, on the Pareto frontier. Claude Fable 5.2 scores 0.851 at $14.51 per task, and Gemini 4 Argon scores 0.802 at $7.88 per task.
2
1
127
15 seconds of motion graphics, no video model — just code from Fable 5.2, and a demo that reportedly burned 4% of a weekly limit.
At that rate, how many passes does a scene get before the week's limit is gone?
2
1
121
Vercel Labs' agent-desktop reads the accessibility tree, not screenshots: each button gets an index, the agent clicks by number. No cursor grab, no window stealing.
The real test is a long session, not one 0.17s click.
Source: @Pluvio9yte on X

1
2
128
Desk, MacBook, light, even Clawd — the Blender room in that demo was reportedly built by Fable 5.2 from a single prompt, run live on stream, and the laptop screen is a web page Claude built.
1
91
OpenAI dots now connect more than 1 computer; you pick 1 per task
→ Step 1: in the ChatGPT app on each computer, open your dot's profile and select Allow
→ Step 2: your dot can build and test your app on a dedicated machine while you keep coding
→ Each thread uses 1 computer at a time; keep that machine online with the ChatGPT app open
I think the second Mac for Xcode tests is the use case: your own screen stays free.
Do you have a spare machine you would hand to an agent?
via @OpenAIDevs


You can now connect multiple local computers to the same dot and choose which one it uses for a task.
It can build and test your app on a dedicated machine while you keep coding on your laptop.
1
103
Codex /voice: 1 key starts a voice conversation in the terminal
→ Step 1: press F8 or type /voice, when your CLI build and session support voice
→ Step 2: /voice mute toggles your mic, /voice stop ends the conversation
→ /voice settings picks the voice for future conversations
I think voice is best for review, not typing code: talk through the diff while you read it.
Would you talk to your coding agent?
via @OpenAIDevs developers.openai.com/codex/…

1
1
101
Someone built a whole game from scratch — models, sounds and textures — and says it all came from one-shot Fable 5.2 prompts with no human feedback. 8 hours, ~$550 at API pricing: ~2.7M output and 445M input tokens, heavily cached. They've posted it to play.
3
119
