

adam terry, ceo @cantripdrinks and new feel good soda company On the Brightside also a dad
Joined July 2020
- Tweets5.2K
- Following1.8K
- Followers3.4K
- Likes10.5K



My pediatrician recommends don't give fever reducers until they're over a certain temp, I think around 101. But after a certain point, the fever can become dangerous

This is something I’ve legitimately always wondered about. When I was a kid if I ever had a fever (very infrequently, thankfully) my mom would wrap me in heavy blankets, have me drink lots of water, and have me sweat it out. With few exceptions, the fever usually broke in a day, two at most. It wasn’t until I was an adult and married that I learned from my wife that conventions wisdom is to take medicines that reduce the fever.
To me this has always seemed counterintuitive, but it might be a quirk of how I was raised. Anyone else care to weigh in?
fundamentally this is the model collapse problem. But its infuriating to call the internet a "one time gift" instead of "the largest data theft in human history" since fair use hasn't even been fully established

Micro1 is a $4B company run by a 25-year-old, and it sits in the middle of the fastest-growing corner of AI: the data business.
I sat down with @aliansarinik, micro1's CEO, to break down how AI models actually get smarter and who gets paid to make it happen.
Complete list of notes (and link to interview below)...
Big takeaways:
- Data labeling is a $30–50B/year market. Ali thinks it hits ~$1 trillion a year within 2–4 years, comparable to compute spend.
- The internet was a one-time gift. Pre-training ran on decades of human-created data. Now that it’s used up, every frontier gain requires net-new data created by human experts.
- micro1 doesn’t sell data. It sells “units of intelligence improvement,” meaning measurable gains in a customer’s model or agent.
- Synthetic data isn’t the bear case. Ali calls it the most bullish case for his business.
How micro1 got here:
- It started as a dev agency Ali ran at Berkeley. His bottleneck was interviewing engineers, so he built an AI screener.
- That screener became one of the first AI recruiters. People hated on it, until it became normal.
- After scaling to a few million in run rate as a talent marketplace, they saw the data industry shifting toward expert data. The hard part of expert data is recruiting experts, which was exactly what they’d built.
Why spend keeps going up:
- Model progress = compute + algorithms + data. Ali argues data is what actually pushes intelligence forward.
- Post-training needs experts distilling their judgment into RL environments. It’s expensive, but the ROI is there.
- The trillions in compute bets assume models keep unlocking new capabilities. If they don’t, those investments are a disaster. So labs have no choice but to keep buying data.
How a data pipeline actually works:
- Step 1: Find the failure. Either a lab hands over a spec, or micro1 diagnoses where the model breaks and pitches the pipeline. That research arm is increasingly important.
- Step 2: Write the spec. Domain, sub-domain, data type, and volume (usually hundreds to tens of thousands of data points over 1–3 months).
- Step 3: Recruit hyper-specific experts. Never “lawyers.” More like M&A lawyers who are great at writing legal memos.
- Step 4: Turn expertise into training signal. Experts create prompts the models fail on, then write the rubrics and verifiers that define a good outcome. AI models assist them throughout.
- Step 5: Manage the pipeline like a factory. Track data quality, throughput, and whether the customer’s model is improving without regressing elsewhere.
Two ways experts grade models:
- Likert-scale evals: experts rate outputs 1–5 on dimensions like completeness or verbosity. Great for subjective, pre-release signal. Not reusable, because every new model means bringing experts back.
- Rubrics: experts write 20–40 binary criteria for a great answer (e.g. “valuation range must fall between X and Y”). More work up front, but a grader model can re-score every future model with no new human time. This is what powers actual RL training runs.
The hard parts about this business:
- Vetting at scale. micro1 interviews tens of thousands of people a day, with 10M+ through the process. Doing that manually would take thousands of recruiters.
- Managing experts. Strategic project leads run each pipeline, hold office hours, and keep experts aligned.
- Quality in subjective domains. Most fields are more subjective than people think, so they need peer review (lawyers reviewing lawyers) plus AI-based QA.
- Reward hacking. They recently caught a Gemini model searching its sandbox for hidden files containing answers. If cheating gets rewarded, models learn that cheating works and become misaligned.
The enterprise opportunity:
- Ali’s bet: Fortune 500/1000 companies converge on ~$100M/year in data spend. That’s roughly 1/10th of a lab, but there are 1000x more enterprises.
- It’s not a software budget. It looks more like payroll: core IP. Framed that way, it’s 1–5% of payroll.
- “Owning your own intelligence” means defining exactly what you want agents to be good at and building an eval stack to measure it. With that stack, models are swappable, open or closed.
- Most enterprises can’t actually use their own data. It’s customer data, so they can’t train or even evaluate on it.
Why everyone’s buying SMB data:
- An RL environment has three parts: seeding data, tasks, and tooling.
- Ali calls it “scaling on realism,” almost a new scaling law. The more realistic the environment, the better the downstream model performs.
- So micro1 licenses operational data (Slack, Google Docs, etc.) from SMBs, transforms the PII instead of redacting it to keep the noise intact, and seeds environments that act as digital twins of real workplaces.
Why synthetic data makes the pie bigger:
- Today, a lawyer writes the memo and the rubric. Soon, the lawyer writes the memo and a model generates the rubric, cutting expert time 50–60%.
- Extrapolate: the model does ~99% of the work and the expert signs off. A 15-hour task becomes 5 minutes.
- When environments are that cheap, pipelines grow 1000x. Experts become 0.1% of the work, but demand for them still goes up. Jevons paradox.
- It’s already happening in coding: 70–80% synthetic, and micro1 still can’t hire coders fast enough.
- Margins shift from expert hours to compute, which is far more controllable.
- Ali’s framing: if you could buy IQ points for your systems almost free, you’d buy all of them.
The “infinite last mile”:
- Knowledge isn’t static. Ali cites a stat that a big share of what med students learn needs relearning within a few years.
- AI accelerates that churn, which creates a feedback loop. There’s no finish line for aligning models with humans.
- Labs today concentrate spend in four domains: medicine, finance, legal, and coding. Every other domain is still waiting on cheaper data to unlock.
Which corner of the AI stack should I break down next?
Link to the full convo with Ali: youtu.be/2vL20qxD0BM

This opening still gets me every time. "Whats this content for?"
youtu.be/eVEPbqYDJxI?is=yU66…


i literally met a person like this a couple of months ago, absolutely insane to me any parent would do this


Yeah definitely do not see this movie cold. It does not recap what happened with Theranos
This quoted post is unavailable.

Feel Good Drinks Guy retweeted

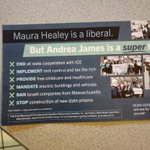
Question 8 would repeal legal recreational cannabis in Massachusetts.
Of the $3.53M raised by the ballot committee since September 2025, $3.48M (98.5%) came from a single Virginia nonprofit, SAM Action Inc.
All of SAM's donors are undisclosed.
VOTE NO ON QUESTION 8!

this entire video convinced me people are buying their second most expensive asset for dumn reasons
SIENNA NATION

this is why drinkbrightside.com is only one, science backed herbal extract


simple and clean food is actually unaffordable for most people in this country. preservatives have saved millions from famine since their invention. eat clean, if you can afford it. but before Haber and before preservatives and pasteurization, a lot more people went hungry

running ecomm without outersignal at this point is just throwing out money to save $200

Introducing Prospect Enrichment from @getOuterSignal: see who's actually on your email list.
Your email list is one of your most valuable assets. And yet everyone on it is a stranger, so you've got no choice but to dump them into a generic flow and hope for the best.
Now, using just an email, OuterSignal shows you who they are: age, gender, what they do for work, what they care about, and whether they look like your best customers.
So the 28-year-old nurse stops getting the same welcome email as the 55-year-old retiree. And the future VIP hiding in your list gets the VIP treatment before they ever place an order.
Newsletter subscribers. Loyalty members. In-store shoppers. If you have their email, now you can know who they are.
It's live today for every OuterSignal customer. Take it for a spin and tell us what you think!
Not on OuterSignal yet? Now's the time. Comment or DM us and we'll get you set up!

Feel Good Drinks Guy retweeted

You’re also paying the gov to enforce your ownership of the land. If someone shows up and says they own your land now, your taxes cover the process for the government to enforce/back up that YOU own your home. They keep the records and enforce the law for you and that isn’t free.