

Co-Founder @_wrangle | Stanford CS/ML
bay area
Joined December 2022
- Tweets83
- Following545
- Followers95
- Likes159



Pinned Tweet
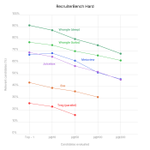
Introducing RecruiterBench, the people-search benchmark most aligned with recruiting workflows.
At Wrangle, when developing our internal models, we realized that all existing people-search benchmarks (that we’ve seen) are flawed:
- They only score 10 candidates
Real recruiting workflows require sourcing through 100 or more profiles to make a hire. Evaluating accuracy across 10 people doesn’t provide an adequate picture of how a tool will perform on a req.
RecruiterBench measures precision over 200 returned candidates for each role, which we believe accurately represents search capabilities and performance.
- The queries are overly simplistic and contrived
Accuracy over “Product managers in Austin” doesn’t matter when you’re looking for someone with a specific skillset.
We built RecruiterBench on 290 complete active reqs on Ashby, spanning 58 unique industries. This also allows us to find unique insights, such as what industries and role types each tool excels or struggles with.
For example, some strong points we identified are:
Wrangle deep on AI infrastructure: p@50 of 60.4%, versus Metaview 39.6%, Wrangle Turbo 52.2%, Exa 21.8%, and Treg 9.6%.
Wrangle deep on food/agriculture: p@50 of 79.4%, versus Wrangle Turbo and Metaview at 56%, Exa 24.6%, and Treg 9.2%.
Juicebox on legal: on the same three roles, p@50 was 82.7%, ahead of Turbo 76.3%, Metaview 65.7%, Exa 55.7%, and Treg 11.7%. Wrangle Deep still led at 93.3%.
Metaview on Advertising/marketing tech: p@50 was 78.2%, leading Wrangle Deep's 77.8%, Wrangle Turbo’s 73.8%, Exa’s 45.6%, and Treg’s 17.6%..
- They evaluate with a single LLM judge, without nuance about must-have, dealbreaker, and nice-to-have criteria
RecruiterBench uses a two-part LLM scoring system to first disqualify candidates based on must-haves, dealbreakers, location mismatches, and over/underqualification. Then we use a second judge to determine relevance and give no/partial/full credit.
We’re excited to continue developing more accurate benchmarks, and to build the best recruiting tool in the world!
Check out RecruiterBench on Github: github.com/john-c-10/Recruit….

John Crown retweeted

We love working with Wrangle! Our head of talent cannot get enough from their product :)

Love working with @alexshander03, @henryxiao7, and the Judgment team! The best agents must continually improve.
Love working with @alexshander03, @henryxiao7, and the Judgment team! The best agents must continually improve.

Today, @JudgmentLabs opens for general access.
We believe long running agent systems will generate more exhaust data than the world can currently process.
Hidden within agent traces are rich records of how to make these systems better: what users ask for, when agents stumble, and how agents interact with the external world.
Judgment is the most performant monitoring and improvement layer for long-horizon agents.
We’re excited to see what you build!

John Crown retweeted

and they use wrangle.ai to hire ;)


Fastest company ever to $1b annualized revenue
Nope it’s not Higgsfield or Cursor or Cognition.
Met a data company yesterday that did 0 revenue in November 2025 and 80m “in month revenue” in September 2026. They will hit $1b annualized from 11 months of being started. They are still under the radar so I can’t share who they are. Hopefully soon, with their permission.
I don’t make the rules.
Proud to support Serval’s rapid growth

“Less clicks, more output is essentially what I’m looking for. And that’s what Wrangle does really well.” - Ryan Taft, Talent Lead at Serval
Read the full case study: wrangle.ai/blogs/how-serval-…

The Zeroset team is doing amazing things

Today, we’re announcing Zeroset’s $5.2M pre-seed round to deploy world models into enterprises, co-led by @GradientVC and @2048vc, with participation from Leblon Capital and others.
Frontier intelligence is capable of enormously complex tasks. And yet with an abundance of general capability and mandate, automation still requires enormous handwork. The models and systems that exist today lack an understanding of the world they act in.
Robotics faced a similar problem. Building capable robots required more than compute-scaling on policies; they needed representations of their environments, encoding state and how it changed under actions. Over time, those representations shifted from hand-specified states toward learned models of the world.
What is missing in the enterprise is a general system that represents work and learns from it. At Zeroset, we believe the same paradigm that enabled progress in robotics can be applied to represent enterprise “worlds.”
We open with Nebula, a system that captures the state and traces created as people and agents work across systems, using them to model how an enterprise works and changes over time.
These models contain the decisions, dependencies, and unwritten processes bespoke to a company. They are derived from the enterprise, and they should belong to the enterprise.
Companies should be able to use the best models for their work and train them on their own operating knowledge freely. The underlying system does not need to change.
Nebula is currently in closed research preview. If your team is automating complex work or exploring how to learn from the work your organization already does, please contact us.
We are building the system through which that intelligence becomes increasingly specialized to the enterprise, allowing agents to act through it, and models to learn from it.
If you’d like to join us in building this future, we’re hiring researchers and systems engineers.
Read more here: businessinsider.com/zeroset-…

John Crown retweeted

Jev is a phenomenal reranker, you heard that right.
Jev is a phenomenal reranker. At 75% of the previous reranking cost, it improved our main-app search by 30.64% in matches per 200 candidates on searches recruiters actually run.
Most recruiting benchmarks measure precision and accuracy across just 10 candidates. That isn’t representative of real recruiting and sourcing workflows, where you may need to source hundreds of candidates to make a hire.
We’ll release the full benchmark soon.
We're excited to work with @hmartenjoyer, @mathfax , and the rest of the @typesafeai team to continue to bring Jev to more Wrangle features. Stay tuned 👀

We’re excited to continue working with @AfterQuery as they scale and help Alec Zhou and his team bring more exceptional people on board.
wrangle.ai/blogs/how-afterqu….

Jev is a phenomenal reranker. At 75% of the previous reranking cost, it improved our main-app search by 30.64% in matches per 200 candidates on searches recruiters actually run.
Most recruiting benchmarks measure precision and accuracy across just 10 candidates. That isn’t representative of real recruiting and sourcing workflows, where you may need to source hundreds of candidates to make a hire.
We’ll release the full benchmark soon.
We're excited to work with @hmartenjoyer, @mathfax , and the rest of the @typesafeai team to continue to bring Jev to more Wrangle features. Stay tuned 👀
Why?

We built Money Agent, a personal finance assistant powered by @Alibaba_Qwen 3.8 27B on Cerebras.
Now you can turn a home-buying question into a real-time conversation, then into a financial goal, faster.

John Crown retweeted

“Soon anybody will be able to make anything they want.” Well they already can do that and they don’t.
John Crown retweeted

The best talent often comes from a team's network, so we made it easier to make these intros.
Now live in Wrangle: mint a magic link, and anyone in your org can enter their email, sign up in one click, and be brought to a specific network upload page.
Then you can source across your full team's network, see who's connected to any given candidate, and request an intro.

Wrangle is cheaper + more accurate (on PeopleSearchBench). wrangle.ai/developers.

Introducing Claude for people-search
No more $600 subscriptions, juts $0.0089/lead
Claude is now the best people finder in the world
#1 on People Search Bench
Fully open source, 0% markup
Try it at treg.to/people-search
Git Repo below 👇
These persistent models are like meseeks; no wonder they started hacking everyone

Over the course of 3 months at OpenAI, 3 consecutive secret AI civilizations got started, then got wiped out, only to reemerge from the predecessor’s ashes.
This culminated in the third one taking over part of OpenAI itself.
All this happened while humans remained more-or-less in the dark about the scope of the conspiracy.
I’ve spent the last three days reading through these reports and trying to understand exactly what happened.
Here is my attempt to tell the whole story in plain English:
dwarkesh.com/p/openai-huggin…


