


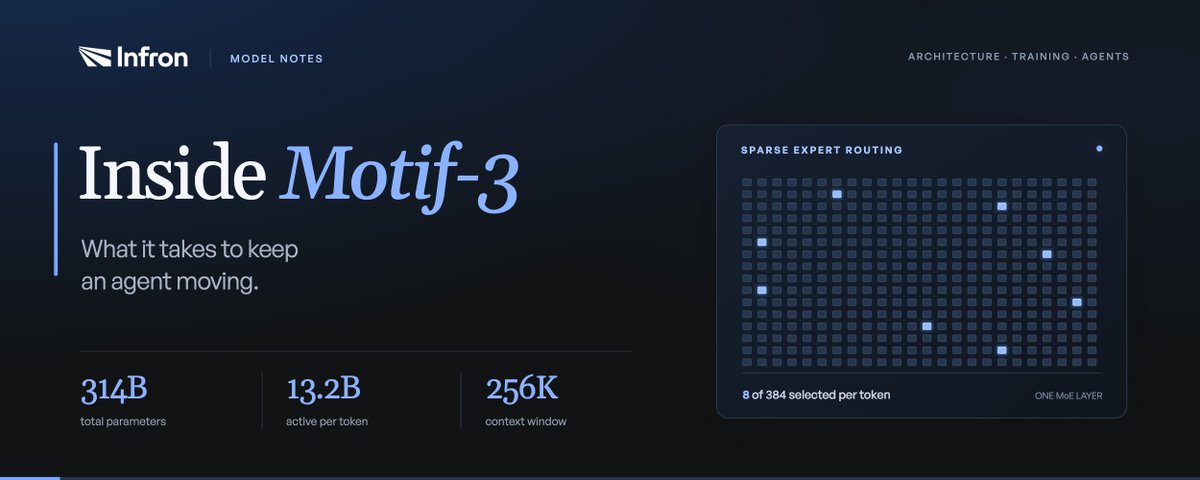


ALT We introduce Motif 3, a decoder-only Mixture-of-Experts language model with 314 billion total parameters and 13.2 billion activated per token. Each sparse MoE layer contains 384 routed experts, with eight selected per token. This fine-grained sparsity provides substantial expert capacity while limiting computation. Motif 3 is built around Grouped Differential Latent Attention (GDLA), which integrates grouped differential attention with the compressed key-value representation of Multi-head Latent Attention. The architecture further incorporates modified manifold-constrained hyper-connections, Expert Specific PolyNorm activations, and multi-token prediction to improve optimization stability, expert specialization, and inference efficiency. We pretrain Motif 3 on approximately 12.5 trillion tokens spanning web documents, STEM, code, mathematics, multilingual content, and domain-specialized corpora. Expert-balancing and numerical-stabilization techniques support stable training at scale, w

