

ECE Ph.D. Student @GeorgiaTech | Synergy Lab | Research: HW-SW Co-Design, Efficient Generative AI, Inference, Model Compression
Atlanta, GA
Joined September 2026
- Tweets22
- Following123
- Followers14
- Likes157


Pinned Tweet
✦ Polestar is accepted at #NeurIPS2026! 🇦🇺🦘🌏
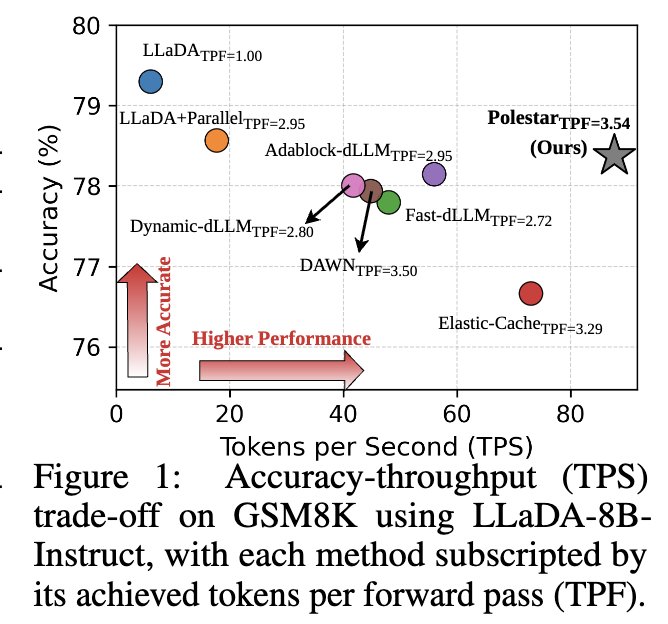
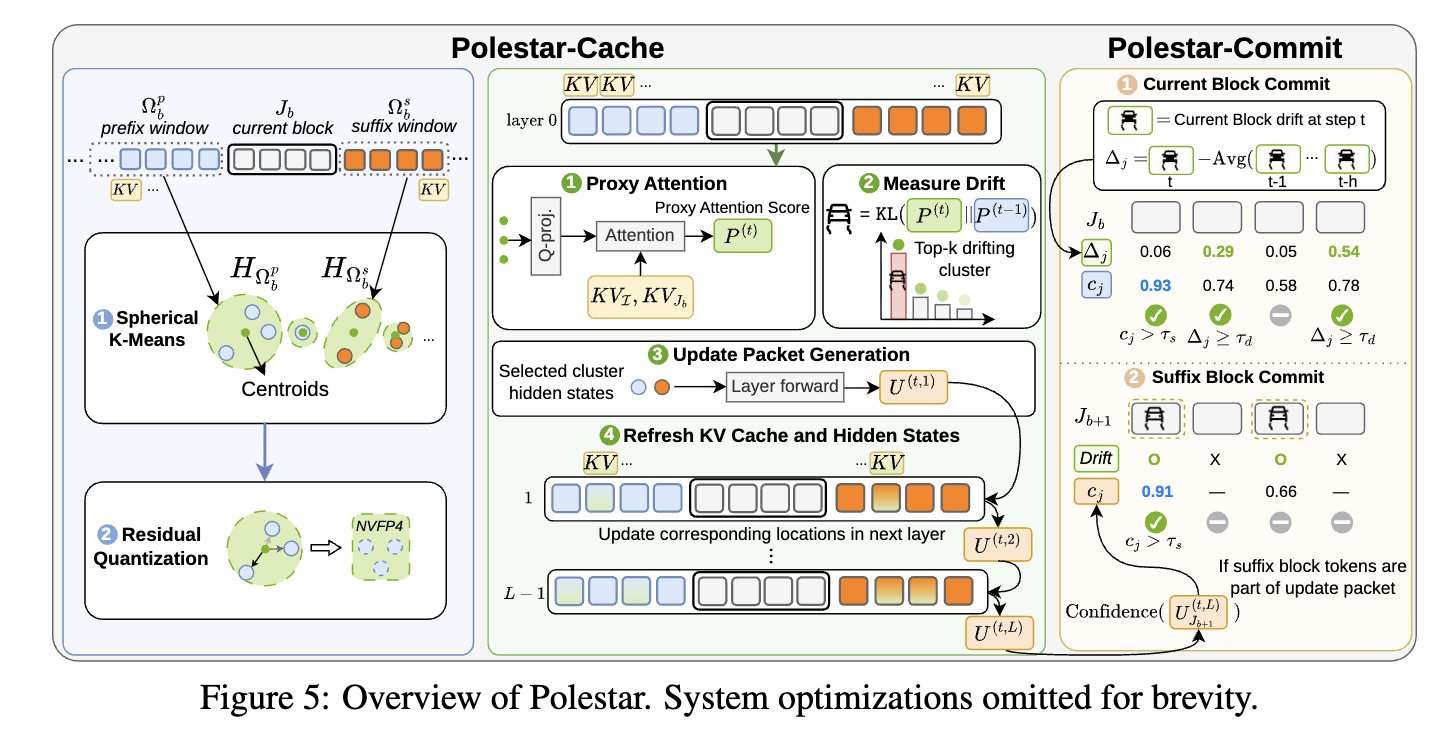
Training-free dLLM acceleration guiding both sparse KV-cache updates & parallel token commitment with a single representation drift signal.
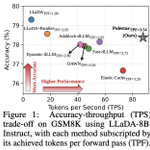
⚡ 20.5× vanilla LLaDA throughput on GSM8K (+higher accuracy!)
Paper, Code & Web 👇
1
130
Mingyu ✈️ NeurIPS26 retweeted

🎉 Heading to NeurIPS?
Given that the main conference is in Sydney this year, we’re giving out travel grants to a limited number of attendees. The application closes at the end of November.
Link to apply: tinyurl.com/neurips-travel-g…

Mingyu ✈️ NeurIPS26 retweeted

Last Year We Built Megakernels. This Year We Deleted Them.
One year ago, we helped introduce some of the first AI megakernels to the world. Since then, we’ve enjoyed seeing their wide adoption from friends and researchers. However, while whole model megakernels are a helpful abstraction, we’ve found that they overcomplicate and are not always an ideal optimization target.
Below, we discuss our journey to understand and push past these limitations. We start with a deep dive into two contrasting paradigms of ML optimization – Torch Compile and Megakernels

Two weeks ago we announced Together Compiler: agents that tune inference to your model, chip, and traffic, for up to 2.6x more throughput.
Today, we’re sharing the journey behind it: the experiments that challenged our assumptions of megakernels, the surprising strengths of Torch Compile, and the lessons that shaped our development of a next-generation system for inference optimization.
Shout out to @dylan__lim @reyna_abhyankar @simran_s_arora and the team!
Read more: together.ai/blog/road-to-tog…

Mingyu ✈️ NeurIPS26 retweeted

Local AI 301: Quantization nitter.cf/i/broadcasts/2rJXOgajp…

Mingyu ✈️ NeurIPS26 retweeted

We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: rikiyat.github.io/blog/weigh…

Readers added context they thought people might want to know
LLM was given weights explicitly as text in prompt and used code/forward passes (per authors' logs) to ablate Qwen looping direction, a known thinking-mode issue per model card. Primarily fixed repetition in that mode, not general 'natively' improving weights/math.
rikiyat.github.io/blog/weight-sp…
github.com/RikiyaT/lm_und…
huggingface.co/Qwen/Qwen3.5-0…
huggingface.co/RikiyaT/Qwen3.…
Mingyu ✈️ NeurIPS26 retweeted

Day 25/
We are doubling all usage limits for all Pro 100/200/500 tiers and Business Premium, effective today.
We heard your kind feedback and won’t be reducing usage limits for Pro 200, so your Work and Codex usage will stay the same. We’re also going to continue offering extended limits for dots for now, and usage of your dot will still continue to be separate from your default usage.
And we'll of course also keep shipping better models and other efficiency improvements that increase your effective usage over time.
Mingyu ✈️ NeurIPS26 retweeted

Announcing Gemini 4 Carbon, our strongest model with state-of-the-art cybersecurity and long horizon capabilities.
Carbon represents a step up across most benchmarks, delivering strong frontier performance in autonomous coding and cyber defense.
We’re first making Carbon available to a subset of trusted cyber defenders in our Fairwind program. We’ll expand access as soon as possible.

Mingyu ✈️ NeurIPS26 retweeted
Day 23/ Much requested iCloud Main & Calendar plugins. Just kidding, today is a reset. Still much requested though!

Mingyu ✈️ NeurIPS26 retweeted

🚀 Introducing Next-Concept Modeling (NCM): our new paradigm for fast, parallel, coarse-to-fine text generation.
Compared to strong diffusion language models (DLMs) at similar parameter size, NCM achieves:
⚡ Up to 31× faster generation on downstream tasks like summarization and machine translation with comparable or better quality.
🏎️ 10–21× faster unconditional generation across TinyStories, LM1B, and OpenWebText, with comparable or better generative perplexity and using 3–5× fewer training tokens.
🧩 Better performance on reasoning tasks like Sudoku, outperforming both AR and diffusion baselines with fewer sampling steps.
With @ishanskhare, @IddahMlauzi, @ekellbuch, @simran_s_arora, @Azaliamirh, and @HazyResearch.
More details in the thread 🧵👇
📄 Paper: arxiv.org/abs/2607.14107
🌐 Web: polestar-dllm.github.io/
💻 Code: github.com/gt-synergy-lab/Po…
Awesome collaboration w/ @_ramakin_, @thisissouvikk, and @tusharkrishna29 at @GeorgiaTech & @IntelAI!

ALT Overview of Polestar method
🎉 Polestar is accepted to #NeurIPS2026!
Can one signal tell a diffusion LLM both when its KV cache is stale and when a token is ready to commit?
Yes: token representation drift.
📄 arxiv.org/pdf/2607.14107🧵
1
116
Why does this work? In bidirectional attention, unmasking one token changes the context, and representation, of others.
We use that drift to:
- refresh stale KV selectively
- commit tokens when drift spikes indicate convergence
Training-free, one signal for both.
1
51