
IEEE/ACM DAC under 40 innovator'25 | INNS Young Investigator'24 | CPAL rising star'25 | SRC Outstanding Researcher'23 | RS @ Intel Labs | Opinions are personal.
Los Angeles(US), Kolkata(IND)
Joined April 2012
- Tweets238
- Following263
- Followers229
- Likes768




SOUVIK KUNDU retweeted

Thank you @JensenHuang for 33 years of bold leadership. You built a small startup into America’s most valuable company, with relentless improvement. Your grit and perseverance should always be remembered. Your personal generosity with time and advice to founders like me has secured a bright future for America and AI.
SOUVIK KUNDU retweeted

📄 Paper: arxiv.org/abs/2607.14107
🌐 Web: polestar-dllm.github.io/
💻 Code: github.com/gt-synergy-lab/Po…
Awesome collaboration w/ @_ramakin_, @thisissouvikk, and @tusharkrishna29 at @GeorgiaTech & @IntelAI!

ALT Overview of Polestar method
SOUVIK KUNDU retweeted

A tool agent spends much of its wall-clock waiting: no next prompt until the last tool call returns.
Liu and Beerel (@USCViterbi) with Kundu (@thisissouvikk, Intel Labs) attack that serial chain with Speculative Macro Commit (SMC), a mechanism inside the executor.
Qwen3.5-27B INT4 is the authoritative actor; Qwen3.5-4B (@Alibaba_Qwen) drafts ahead and pre-executes future tool calls on an isolated environment snapshot. Offline, SMC mines recurring multi-call skeletons from traces and keeps those the drafter reproduces reliably.
The commit rule: when the actor's next call matches the drafter's first call (the anchor), the executor commits the rest of the matched macro, calls plus observations, to the official history. Skipped steps never reach the big model. The actor sees the same tool schema; exposing macros as meta-tools did not help, Qwen3.5-27B rarely picked them.
A staged audit (100 held-out tau2 Telecom tasks) shows why: a library match alone predicts the exact future in 34.6% of events. Drafter execution lifts it to 70.6%, the verified anchor to 87.9%, a minimum skip depth to 90.4%.
tau2 Telecom: 18.6% lower latency than sequential, identical outcomes on all 2,285 tasks. AppWorld: 44.9% lower wall time, 68 of 168 tasks completed against 70. Speculative runs use three GPUs, the baseline one.
An earlier build committed almost 2x the macros and ran 1.6% slower than one-step speculation. What pays is a guarded, deep commit on the critical path.
arXiv 2609.03236


Those who are submitting #NeurIPS2026 rebuttal, for my AC lot 3.67 is the highest, 2.7 is the mean score.
4
339
SOUVIK KUNDU retweeted

Polestar measures KL drift to prune stale KV cache and commit converged tokens, achieving 3.67 TPF with zero accuracy loss, all without additional training.
geepity.com/2607.14107/

As rightly said @BeidiChen . A fruitful collaboration with the infinity lab @CMU.

Rollout generation is becoming a central bottleneck in long-context RL says everyone — and recent efforts from Cursor @cursor_ai and Fireworks @FireworksAI_HQ
show how just important disaggregating rollout and training is today.
Excited to share Sparrow🐤, which makes sparse rollout practical and accelerate stable long-context RL.
Check it out!
1
120
#MLSys2026 #ReasoningEfficiecy #LRMKVcache #KVcacheEviction
As the MLSys 2026 has kick started, our work on Large Reasoning Model KV Cache Eviction will be presented at the venue! Feel free to stop by during tomorrow's presentation session!
ℙ𝕒𝕡𝕖𝕣 𝕥𝕚𝕥𝕝𝕖: 𝗦𝗸𝗶𝗽𝗞𝗩: 𝗦𝗲𝗹𝗲𝗰𝘁𝗶𝘃𝗲 𝗦𝗸𝗶𝗽𝗽𝗶𝗻𝗴 𝗼𝗳 𝗞𝗩 𝗚𝗲𝗻𝗲𝗿𝗮𝘁𝗶𝗼𝗻 𝗮𝗻𝗱 𝗦𝘁𝗼𝗿𝗮𝗴𝗲 𝗳𝗼𝗿 𝗘𝗳𝗳𝗶𝗰𝗶𝗲𝗻𝘁 𝗜𝗻𝗳𝗲𝗿𝗲𝗻𝗰𝗲 𝘄𝗶𝘁𝗵 𝗟𝗮𝗿𝗴𝗲 𝗥𝗲𝗮𝘀𝗼𝗻𝗶𝗻𝗴 𝗠𝗼𝗱𝗲𝗹𝘀
ℙ𝕣𝕖-𝕡𝕣𝕚𝕟𝕥: lnkd.in/guxTY-BY
ℂ𝕠𝕕𝕖: lnkd.in/gPYhs5Uq
𝕊𝕖𝕤𝕤𝕚𝕠𝕟: Research Track Oral Presentation- LLM Serving 3
𝕋𝕚𝕞𝕖: 1:30 - 3:00 pm, May 20 2026
𝕋𝕃, 𝔻ℝ:
• SkipKV yields up to 26.7% higher accuracy vs SoTA LRM KV compression method (R-KV)
• 9.6x throughput gain vs. FullKV
• 1.6x shorter generation length
#ICML2026 #ICMLWorkshop2026 #SCALEWorkshop #MultimodalAI #AgenticAI #MachineLearning
🚀🚀Decisions are out for the ICML 2026 Workshop on 𝗦𝗰𝗮𝗹𝗮𝗯𝗹𝗲 𝗟𝗲𝗮𝗿𝗻𝗶𝗻𝗴 𝗮𝗻𝗱 𝗢𝗽𝘁𝗶𝗺𝗶𝘇𝗮𝘁𝗶𝗼𝗻 𝗳𝗼𝗿 𝗘𝗳𝗳𝗶𝗰𝗶𝗲𝗻𝘁 𝗠𝘂𝗹𝘁𝗶𝗺𝗼𝗱𝗮𝗹 𝗔𝗜 𝗔𝗴𝗲𝗻𝘁𝘀!
🎉🎉A huge thanks to everyone who submitted, reviewed, and supported the workshop. We are thrilled to share the outcome of an incredibly engaging review cycle.
🌟𝗪𝗵𝗮𝘁'𝘀 𝗡𝗲𝘅𝘁: 𝗪𝗼𝗿𝗸𝘀𝗵𝗼𝗽 𝗦𝗰𝗵𝗲𝗱𝘂𝗹𝗲
━━━━━━━━━━━━━━━━━━━━━━━━
🗓️Instructions to accepted papers: May 18, 2026
🗓️Camera-ready Due: June 5, 2026
🗓️Workshop Day: July 10, 2026
📍Venue: ASEM Ballroom 201, COEX Convention and Exhibition Center, Seoul, South Korea
🌟𝗢𝘂𝗿 𝗟𝗶𝘀𝘁 𝗼𝗳 𝗦𝗽𝗲𝗮𝗸𝗲𝗿𝘀
━━━━━━━━━━━━━━━━━━━━━━━━
@dasongle (GenBio), @mohitban47 (UNCCH), @james_y_zou (Stanford), @chelseabfinn (Stanford), @MengdiWang10 (Princeton), @sunjiao123sun_(Google), @MikeShou1 (NUS), @MinhyukSung (KAIST)
🌟𝗟𝗶𝗻𝗸𝘀
━━━━━━━━━━━━━━━━━━━━━━━━
Website: lnkd.in/g__9vvdB
Discord: lnkd.in/gMk_kThK
Contact: [email protected]
🎉🎉Congratulations to all accepted authors, and to those whose papers were not accepted this round, we hope the detailed reviews are helpful for your future submissions.🎉🎉
🚀🚀See you at #ICML2026!
🌟𝗪𝗶𝘁𝗵 𝗼𝗿𝗴𝗮𝗻𝗶𝘇𝗲𝗿𝘀:
━━━━━━━━━━━━━━━━━━━━━━━━
@HongyiWang10, @digbose92, @jaeh0ng_yoon @ManlingLi_, @nagsayan112358, @schowdhury671
🤖 Made with AI

The CPU Bottleneck in Agentic AI and Why Server CPUs Matter More Than Ever ! thanks for the blog of our work @vikramskr
open.substack.com/pub/viksne…
(📄paper link: arxiv.org/pdf/2511.00739)

81
SOUVIK KUNDU retweeted

Paper submissions are open for #ICML2026 Workshop: #SCALE
𝗜𝗺𝗽𝗼𝗿𝘁𝗮𝗻𝘁 𝗱𝗮𝘁𝗲𝘀:
Submission open: April 06, 2026 (AoE)
Submission close: April 28, 2026 (AoE)
Decision: May 15, 2026 (AoE)
𝗦𝘂𝗯𝗺𝗶𝘀𝘀𝗶𝗼𝗻: openreview.net/group?id=ICML…
𝗪𝗲𝗯𝘀𝗶𝘁𝗲: scale-icml-2026.github.io
#AgenticAI #CPUbottleneck #AI_Workload #isCPUthebottleneck
As we are scrolling through all the latest and greatest developments in the fast paced AI world, one question may come more as a confusion as opposed to a clear understanding:
𝗪𝗵𝘆 𝘀𝘂𝗱𝗱𝗲𝗻𝗹𝘆 𝗖𝗣𝗨 𝗵𝗮𝘀 𝘁𝗮𝗸𝗲𝗻 𝘁𝗵𝗲 𝗰𝗲𝗻𝘁𝗲𝗿 𝘀𝘁𝗮𝗴𝗲 𝗶𝗻 𝗔𝗜 𝘄𝗼𝗿𝗸𝗹𝗼𝗮𝗱 𝗲𝘅𝗲𝗰𝘂𝘁𝗶𝗼𝗻?
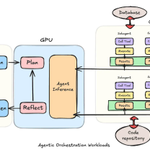
As we roller-costar into a new era of AI, namely the "Agentic AI", we see a new and quite interesting bottleneck, namely the CPU. The role of CPU in the spectrum of AI, has been largely latent! However, Agentic AI has been shifting the narrative, quite rapidly. To understand, this key shift, we present a comprehensive benchmarking (and potential solutions) for Agentic AI with few key findings.
Work done in collab with @Ritikraj from Georgia Tech who has led this "important and timely" work (started during his internship with Intel), along with Prof. @tusharkrishna29 !!!
🌟Paper: 𝗧𝗼𝘄𝗮𝗿𝗱𝘀 𝗨𝗻𝗱𝗲𝗿𝘀𝘁𝗮𝗻𝗱𝗶𝗻𝗴, 𝗔𝗻𝗮𝗹𝘆𝘇𝗶𝗻𝗴, 𝗮𝗻𝗱 𝗢𝗽𝘁𝗶𝗺𝗶𝘇𝗶𝗻𝗴 𝗔𝗴𝗲𝗻𝘁𝗶𝗰 𝗔𝗜 𝗘𝘅𝗲𝗰𝘂𝘁𝗶𝗼𝗻: 𝗔 𝗖𝗣𝗨-𝗖𝗲𝗻𝘁𝗿𝗶𝗰 𝗣𝗲𝗿𝘀𝗽𝗲𝗰𝘁𝗶𝘃𝗲
🌟Arxiv: lnkd.in/g69jSnMC
🌟Code: to be released soon!
🌟🌟🌟𝗞𝗲𝘆 𝘁𝗮𝗸𝗲𝗮𝘄𝗮𝘆𝘀:🌟🌟🌟
🚀For Agentic workloads, tool processing on CPUs can take significant chunk of E2E latency, motivating a CPU-centric optimization strategy.
🚀A system with high performance CPU and non-SoTA GPU often match a system with high performance GPU in E2E latency on such tool-dominated agentic AI workloads motivating cost-effective agentic AI deployments.
🚀High performance GPU system can shift the bottleneck from GPU to CPU when tool execution latency is comparable to LLM inference latency, making them more CPU-bounded than systems with non-SoTA GPU, motivating system-aware optimization strategies.
🚀In agentic AI workloads, CPUs may prematurely saturate the throughput, subsequently bottle-necking the system and degrading the utilization of costly GPU resources.
[ 𝑁𝐵: 𝑡ℎ𝑒 𝑏𝑒𝑛𝑐ℎ𝑚𝑎𝑟𝑘 𝑟𝑒𝑠𝑢𝑙𝑡𝑠 𝑎𝑟𝑒 𝑝𝑒𝑟𝑓𝑜𝑟𝑚𝑒𝑑 𝑖𝑛 𝑎𝑐𝑎𝑑𝑒𝑚𝑖𝑐 𝑎𝑚𝑏𝑖𝑒𝑛𝑐𝑒, 𝑎𝑛𝑑 𝑛𝑜𝑡 𝑏𝑒 𝑢𝑠𝑒𝑑 𝑓𝑜𝑟 𝑎𝑛𝑦 𝑏𝑢𝑠𝑖𝑛𝑒𝑠𝑠 𝑜𝑟 𝑜𝑓𝑓𝑖𝑐𝑖𝑎𝑙 𝑟𝑒𝑝𝑟𝑒𝑠𝑒𝑛𝑡𝑎𝑡𝑖𝑜𝑛 𝑝𝑢𝑟𝑝𝑜𝑠𝑒, 𝑤𝑖𝑡ℎ𝑜𝑢𝑡 𝑡ℎ𝑒 𝑐𝑜𝑛𝑠𝑒𝑛𝑡 𝑓𝑟𝑜𝑚 𝑡ℎ𝑒 𝑐𝑜𝑟𝑟𝑒𝑠𝑝𝑜𝑛𝑑𝑖𝑛𝑔 𝑎𝑢𝑡ℎ𝑜𝑟𝑠: @𝑅𝑖𝑡𝑖𝑘 𝑅𝑎𝑗 (𝐺𝑎𝑡𝑒𝑐ℎ) 𝑎𝑛𝑑 @𝑆𝑜𝑢𝑣𝑖𝑘 𝐾𝑢𝑛𝑑𝑢 (𝐼𝑛𝑡𝑒𝑙)!]

1
83
#ICML2026 #ICMLWorkshop2026 #SCALEWorkshop #AgenticAI
Paper submission link is now live for our ICML Workshop on Multi-modal Agentic AI: Scalable Learning and Optimization for Efficient Multimodal AI Agents (SCALE)
🌟𝗜𝗺𝗽𝗼𝗿𝘁𝗮𝗻𝘁 𝗱𝗮𝘁𝗲𝘀 𝗮𝗻𝗱 𝗱𝗲𝗮𝗱𝗹𝗶𝗻𝗲𝘀:
======================
🗓️Submission open: April 06, 2026 (AoE)
🗓️Submission close: April 24, 2026 (AoE)
🗓️Decision notification: May 15, 2026 (AoE)
🌟𝗢𝗽𝗲𝗻𝗥𝗲𝘃𝗶𝗲𝘄 𝗦𝘂𝗯𝗺𝗶𝘀𝘀𝗶𝗼𝗻 𝗹𝗶𝗻𝗸:
lnkd.in/gCCffbck
🌟𝗪𝗲𝗯𝘀𝗶𝘁𝗲: lnkd.in/g__9vvdB
🌟𝗝𝗼𝗶𝗻 𝘁𝗵𝗲 𝗗𝗶𝘀𝗰𝗼𝗿𝗱 𝗰𝗵𝗮𝗻𝗻𝗲𝗹: lnkd.in/gJ4yc7vV
For any query please reach us at the discord channel or google group email: [email protected]
Also, in case you want to participate in the process of reviewing, please fill up the following form.
🌟𝗥𝗲𝘃𝗶𝗲𝘄𝗲𝗿 𝗿𝗲𝗴𝗶𝘀𝘁𝗿𝗮𝘁𝗶𝗼𝗻 𝗹𝗶𝗻𝗸:
lnkd.in/g_2jxt6w
With
@HongyiWang10
@digbose92
@jaeh0ng_yoon
@ManlingLi_
@nagsayan112358
@schowdhury671

🎉🎉Announcing #ICML2026 workshop on "Multi-Modal Agentic AI": scale-icml-2026.github.io/
Topics covered: 1. Agentic memory, 2. Efficient agentic AI systems, 3. Scaling of multi-modal agents, 4. Agents for Planning, 5. Evaluation, guard railing, and benchmarking of agents
🚀Confirmed speakers: @dasongle (GenBio) @mohitban47 (UNCCH) @james_y_zou (Stanford) @chelseabfinn (Stanford) @MengdiWang10 (Princeton) @sunjiao123sun_ (Google) @MikeShou1 (NUS) @MinhyukSung (KAIST)
With @HongyiWang10 @digbose92 @jaeh0ng_yoon @ManlingLi_ @nagsayan112358 @schowdhury671
#AgenticAI #MAS #MultimodalAI

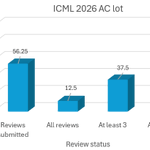
As the #ICML2026 review deadline is approaching (in a day), here is the current status of my AC lot. Seems like it is a race against time now. Overall, we need to chase down around 44% of the missing reviews in a day. With only 12.5% paper receiving all four reviews: God bless peer reviewing, long live human reviews.

316
#KnowledgeDistillation does have scalable impact both +ve and -ve... I recall one of the very first papers (in our group) in the context of @AnthropicAI 's post!


5
124
SOUVIK KUNDU retweeted

A little late on the update, but thrilled to share that PRISM has been accepted at #ICLR2026 @iclr_conf 🎉
Huge thanks to Prof. Eric Xing (@ericxing) and Dr. Souvik Kundu (@thisissouvikk) for their mentorship and support throughout this work. #MultimodalRAG #RAGforScience
1/n 🧵
