

Gamer | Reader | Hugging Face Builder
İstanbul, Türkiye
Joined December 2016
- Tweets9.3K
- Following1.2K
- Followers2.5K
- Likes85.4K







Nusret retweeted

Atatürk'ün cenaze törenine dair pek çok kayıt ve fotoğraf gördüm. Ama beni en çok hüzünlendiren bu fotoğraf oldu.
Anadolu'nun asil köylü kadınları, bebekleri kucaklarında tren yoluna çıkmış Atatürk'ün tabutunu Ankara'ya götüren treni bekliyor. Geçerken bir iki saniyeliğine de olsa görebilmek için...
Vatanlarını düşmandan kurtarmış Halaskar'a son defa selam durabilmek için...


Nusret retweeted

Şu an bir Kaggle yarışmasıyla uğraşıyorum, yaptığım çalışmalar da daha çok onun için:
kaggle.com/competitions/gemm…
Yazı konusunda daha bir şey çıkaramam ama aşağıdaki kaynakları faydalı buldum:
huggingface.co/spaces/FineEn…
huggingface.co/blog/harness-…
github.com/thinking-machines…
Ayrıca ARC-AGI'den sonuçlar paylaşıldıkça onları okuyorum. Data toplama, speed up, fine-tuning vs. güzel insight'lar var.
kaggle.com/competitions/arc-…
kaggle.com/competitions/arc-…

Nusret retweeted

phd nefretini ve bu dramaların etrafında konumlanan insanları anlamakta çok zorluk çekiyorum. kimseyi hedef göstermeye çalışmıyorum ama acaba spesifik bir alandaki phd'li bir insanın o alanda sizden birkaç kat fazla "şey" bilmesi normal olabilir mi?
ortak bir zeminde çok güzel tartışmalar dönebilir, çok da keyifli olur ama konuyla hiç alakası olmayan toksik twitter kişilerinin olaya taraftarlık yapması çok garip.
Nusret retweeted

Day 28/ tibo's game has landed
i spent $5.99 on this domain, but i had a blast making it with grok bot and cursor! i hope you enjoy it and find all the easter eggs 🤍
if i did it right you should be able to play it inside of X too
tibo.dog

Nusret retweeted

Your LLM eval is probably lying to you.
Here are 4 ways it happens, and the cheap habits that catch each one. From my AI Connect Istanbul talk, with code you can run in seconds 🧵
Nusret retweeted

every ai team ships changes all the time. a new model, a new tool, a prompt edit
each one can fix one bug and quietly break another
the agent harness makes your model useful. the eval harness tells you what broke before a customer does


Nusret retweeted

90% of AI Engineer interviews in 2026 are just these 15 concepts repeated:
1/ Transformers & LLM Fundamentals: how LLMs predict the next token, self-attention, multi-head attention, positional encoding, and why transformers replaced RNNs
2/ Tokenization & Embeddings: BPE, how text becomes tokens, and how vectors capture meaning
3/ Prompt Engineering: system prompts, few-shot learning, chain-of-thought, and structured outputs (JSON/schema)
4/ RAG: chunking strategies, retrieval, context injection, context windows, and why RAG beats fine-tuning for fresh data
5/ Vector DBs & Search: vector databases, semantic search, hybrid search , reranking, and HNSW indexes
6/ Function Calling, Tool Calling & MCP: how LLMs trigger APIs, code and databases, and the standard protocol for connecting them
7/ AI Agents & Agentic Workflows: plan, act and observe loops, orchestrated multi-step pipelines, and AI coding agents
8/ Memory & Multi-Agent Systems: short-term and long-term memory, and specialized agents collaborating on a task
9/ Fine-Tuning: full fine-tuning, LoRA, QLoRA, PEFT, and when to fine-tune vs prompt vs RAG
10/ Alignment & Distillation: RLHF, DPO, and knowledge distillation (big model teaches small model)
11/ Quantization & Model Compression: INT8/INT4, pruning, sparsity, and the quality vs speed vs cost tradeoff
12/ Inference & Serving: prefill vs decode, KV cache, speculative decoding, LLM serving, vLLM, batching, and model routing
13/ Multimodal AI & Vision-Language Models: text, image, audio and video in one system, and models that see and reason about images
14/ Evals & Hallucination Detection: LLM evaluation, LLM-as-judge, prompt evaluation, and catching confident but wrong answers
15/ Safety, Observability & Production: guardrails, AI safety, prompt injection, tracing, cost optimization, and production GenAI systems
Know these 15 deeply and you can crack most AI engineer interviews
Nusret retweeted

🚀 Introducing Next-Concept Modeling (NCM): our new paradigm for fast, parallel, coarse-to-fine text generation.
Compared to strong diffusion language models (DLMs) at similar parameter size, NCM achieves:
⚡ Up to 31× faster generation on downstream tasks like summarization and machine translation with comparable or better quality.
🏎️ 10–21× faster unconditional generation across TinyStories, LM1B, and OpenWebText, with comparable or better generative perplexity and using 3–5× fewer training tokens.
🧩 Better performance on reasoning tasks like Sudoku, outperforming both AR and diffusion baselines with fewer sampling steps.
With @ishanskhare, @IddahMlauzi, @ekellbuch, @simran_s_arora, @Azaliamirh, and @HazyResearch.
More details in the thread 🧵👇

Nusret retweeted

welcome to the 9th annual @stateofai report!
ai building better ai, world models, physical ai, geopolitics, cyber defense and 12-month predictions.
read it at stateof(dot)ai or watch my editor’s cut here.
a few of this year’s biggest findings follow:
Nusret retweeted

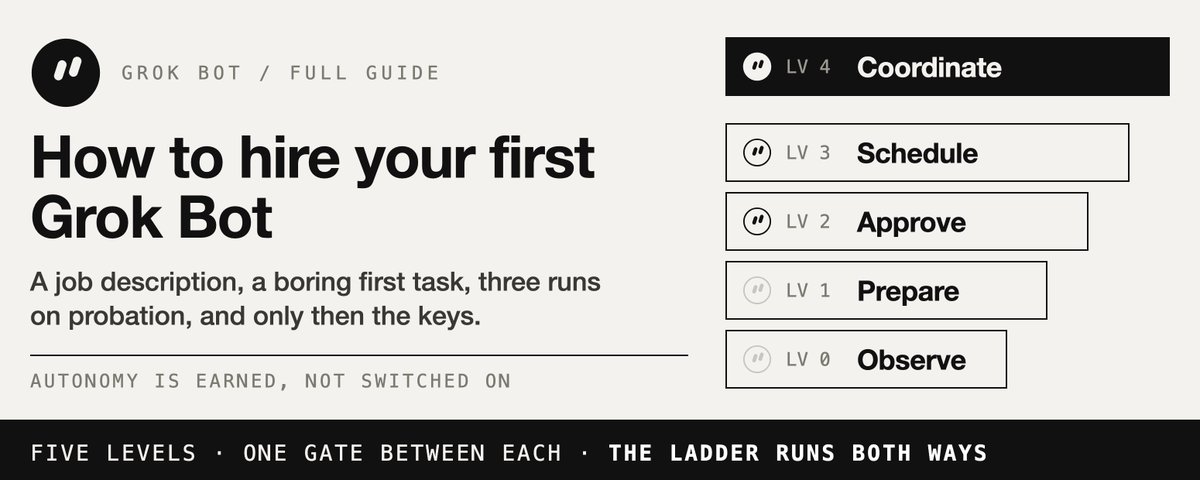
Grok Bot could be the first thing you hire instead of prompt
It can own a job, work inside your tools for hours and come back with finished work
In this article, I show you how
Nusret retweeted

Yani çok iyi çocuksun ama ben ilişki düşünmüyorum ben birini hayatımda istemiyorum dediğiniz erkekler mi

Nusret retweeted

We’re releasing Olmo-core 3—open training infrastructure for large mixture-of-experts (MoE) models.
It’s a core system behind the next generation of Olmo, designed to scale into the trillion-parameter range. 🧵
💻 GitHub repo: github.com/allenai/olmo-core

Nusret retweeted

‼️The Bitter Lesson for context management: Giving LMs unrestricted control over their context beats human-designed SOTA!
Introducing 🩵Context Language Models (CLMs)🩵
- Natively manage their own context
- Treat context as a file
- Learn policies in CLM weights, no harness

Nusret retweeted

Bir yıllık model inference loglarını içeren bir veriseti paylaşıldı. 6.12 milyar istek ve 9 bin farklı modele ait veri içeriyor.
Link: data.agentic-system.org/

Nusret retweeted

Meta's team proposes DCE + SRCL as an alternative to on-policy self-distillation (OPSD).
Achieved significant gains: 30.76% avg acc -> 65.97% on Qwen3-8B
arxiv.org/abs/2609.30652
