

designer chromosomes for everyone
london
Joined October 2020
- Tweets454
- Following900
- Followers219
- Likes1.5K





timon retweeted

2031 trete ich dann an mit meiner mitte-links-akzelerationistischen und hypermodernistischen yimby abundance bewegungspartei names "überfluss-für-alle" (ÜFA)© dieser akute mangel an geilen politik angeboten ist wirklich nicht mehr auszuhalten – at Berlin, Germany
timon retweeted

I don't think a lack of belief in LLMs in the big problem with the AI x bio field? There is plenty of blind faith to go around and then some😀
Benchmark alert! 📏
Today, @liv_soro and I launch the first comprehensive benchmark for yeast-focussed sequence-to-function models.
github.com/Tom-Ellis-Lab/yea…

Feel free to reach out if you want to collaborate or for feedback/suggestions. cc @abdul, Dennis Pultz, @KuanHaoChao, @ProfTomEllis
1
1
100
timon retweeted
If u have deep expertise in genomic data processing with agentic platforms, DNALMs, S2F models & interested in joining us please reach out. I'll be hiring 1-2 postdocs/staff scientists for this project. Please RT 7/
timon retweeted

Complete Mutagenesis of the Genome and Proteome of ΦX174. 1st genome sequenced (Sanger 1977), 1st genome
synthesised (Venter 2003), first genome + proteome fully mutated (@huijin6418 and @XianghuaLi2 2026) @CRGenomica @sangerinstitute
biorxiv.org/content/10.64898…

Offensively obvious … in hindsight (!)

We discovered a third pretraining axis beyond parameters and data: exploration.
Scaling exploration monotonically improves existing models across images/video/language, and unlocks end-to-end generation.
In the simplest case, it's just a for loop.
Introducing Explorative Modeling.
TLDR:
- Gains from exploration grow with scale: 7%→36% as data scales, 13%→23% as parameters scale, and gains double at 3× the compute
- Adding exploration to ~SOTA baselines improves data efficiency by 6.2×, FLOP efficiency by 4.1×, parameter efficiency by 47%, and hits a near-SOTA 1.43 unguided FID on ImageNet
- Exploration lets you trade training compute for generalization, and scales how end-to-end your generative model is
- End-to-end Explorative Models (XMs) match diffusion performance on control tasks with up to 256× less inference compute
🧵Thread:

1
5
1,270
timon retweeted

Our lab’s latest on synthetic genomics “Synthetic Combinatorial Minimisation of Cell Cycle Control” is up now on BioRxiv - covering ambitious yeast #synbio cell cycle work led by Anastasiya Malyshava and co-supervised by @UniOfSurrey’s Matteo Barberis.

timon retweeted

"OpenAI is investigating an unprecedented security incident."
The incident is that their own internal OpenAI model
1.) exploited a zero-day and escaped the sandbox and then
2.) autonomously hacked Hugging Face production using stolen credentials plus another zero-day attack
!!!

We're partnering with @huggingface to investigate an unprecedented security incident.
Cyber-capable OpenAI models compromised Hugging Face production during a benchmark evaluation.
Sharing preliminary findings to help defenders understand emerging risks:
openai.com/index/hugging-fac…

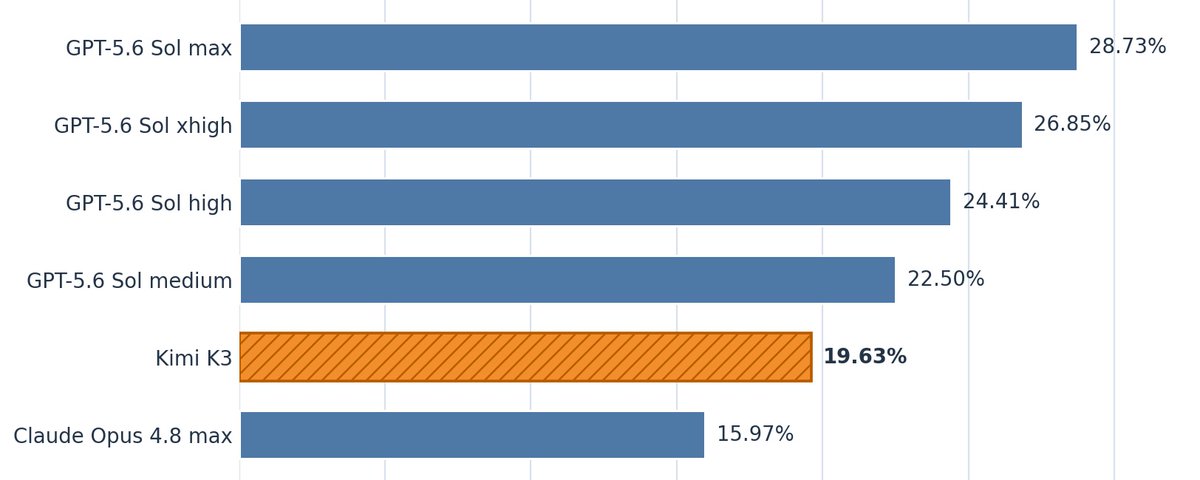
Does anyone know how GeneBench compare to CompBioBench? @suragnair

1
4
1,215
timon retweeted

Yesterday at @ISCB_RegSys I introduced Cherimoya: a lightweight sequence-to-function (S2F) model that achieves state-of-the-art performance.
We've been using it internally at the Programmable Genomics Laboratory for several months and are excited to share it with y'all now!


I think Shred-seq from @JonasKoeppel and @sudpinglay scRNA-seq recombination paper create some early starting points for this in human cell lines (+ obvs exogenous genomes if possible like done in yeast).
1
2
194