
PhD student @VT_CS, supervised by @tuvllms. Interested in search-augmented LLMs. Ex AI resident @VinAI_Research
Blacksburg, VA
Joined July 2023
- Tweets31
- Following637
- Followers106
- Likes115


Thinh retweeted

📢 New Preprint Alert
@SharmaRituraj19 found out a hidden supervision flaw in Looped Language Models: hidden-state norms can grow across iterations, but the LM head hides this from the loss. Exposing or controlling the scale yields more stable training and stronger performance.👇
Paper: arxiv.org/abs/2606.24898
Code: github.com/Rituraj003/readou…


Thinh retweeted
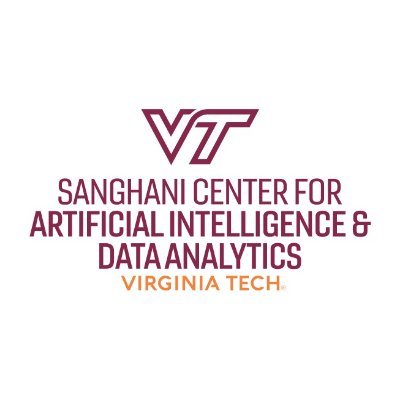
Ph.D. student Thinh Pham (@thinhphp_vt) @VT_CS @SanghaniCtrVT presented his collaborative work, "SealQA: Raising the Bar for Reasoning in Search-Augmented Language Models," during a poster session at #ICLR2026 in Rio de Janeiro.
🔗to paper: arxiv.org/abs/2506.01062


Come checkout our posters at #ICLR2026 🇧🇷!
April 23, 10:30 AM - 1:00 PM
📍Pavilion 3 P3-#1424
SealQA: Raising the Bar for Reasoning in Search-Augmented Language Models (arxiv.org/abs/2506.01062)
I'm also looking for opportunities this summer and would love to connect and chat!

Thinh retweeted
MERRIN
A Benchmark for Multimodal Evidence Retrieval and Reasoning in Noisy Web Environments
paper: huggingface.co/papers/2604.1…

Thinh retweeted

🚨 Excited to announce MERRIN: a human-annotated, expert-vetted benchmark for Multimodal Evidence Retrieval and Reasoning in Noisy Web Environments! 🌐🔍
The web is noisy, conflicting, and multimodal. Even strong search agents fail when questions require reasoning across text, images, video & audio — MERRIN is built to diagnose exactly where they break down, via multi-hop reasoning on open-web search without explicit references to specific modality sources.

Thinh retweeted
Very impressive results from Chroma Context-1, which push the Pareto frontier of agentic search on our SealQA (Seal-0) & LongSealQA benchmarks. Check out their techical report below 👇
trychroma.com/research/conte…


Thinh retweeted

Much like the switch in 2025 from language models to reasoning models, we think 2026 will be all about the switch to Recursive Language Models (RLMs).
It turns out that models can be far more powerful if you allow them to treat *their own prompts* as an object in an external environment, which they understand and manipulate by writing code that invokes LLMs!
Our full paper on RLMs is now available—with much more expansive experiments compared to our initial blogpost from October 2025!
arxiv.org/pdf/2512.24601

Thinh retweeted

🚀 Hello, Kimi K2 Thinking!
The Open-Source Thinking Agent Model is here.
🔹 SOTA on HLE (44.9%) and BrowseComp (60.2%)
🔹 Executes up to 200 – 300 sequential tool calls without human interference
🔹 Excels in reasoning, agentic search, and coding
🔹 256K context window
Built as a thinking agent, K2 Thinking marks our latest efforts in test-time scaling — scaling both thinking tokens and tool-calling turns.
K2 Thinking is now live on kimi.com in chat mode, with full agentic mode coming soon. It is also accessible via API.
🔌 API is live: platform.moonshot.ai
🔗 Tech blog: moonshotai.github.io/Kimi-K2…
🔗 Weights & code: huggingface.co/moonshotai


Thinh retweeted

OpenAI realesed new paper.
"Why language models hallucinate"
Simple ans - LLMs hallucinate because training and evaluation reward guessing instead of admitting uncertainty.
The paper puts this on a statistical footing with simple, test-like incentives that reward confident wrong answers over honest “I don’t know” responses.
The fix is to grade differently, give credit for appropriate uncertainty and penalize confident errors more than abstentions, so models stop being optimized for blind guessing.
OpenAI is showing that 52% abstention gives substantially fewer wrong answers than 1% abstention, proving that letting a model admit uncertainty reduces hallucinations even if accuracy looks lower.
Abstention means the model refuses to answer when it is unsure and simply says something like “I don’t know” instead of making up a guess.
Hallucinations drop because most wrong answers come from bad guesses. If the model abstains instead of guessing, it produces fewer false answers.
🧵 Read on 👇


Thinh retweeted

New paper! We explore a radical paradigm for AI evals: assessing LLMs on *unsolved* questions.
Instead of contrived exams where progress ≠ value, we eval LLMs on organic, unsolved problems via reference-free LLM validation & community verification. LLMs solved ~10/500 so far:


Thinh retweeted
Excited to share that our paper on efficient model development has been accepted to #EMNLP2025 Main conference @emnlpmeeting. Congratulations to my students @linusdd44804 and @Sub_RBala on their first PhD paper! 🎉

🚨 New paper 🚨
Excited to share my first paper w/ my PhD students!!
We find that advanced LLM capabilities conferred by instruction or alignment tuning (e.g., SFT, RLHF, DPO, GRPO) can be encoded into model diff vectors (à la task vectors) and transferred across model versions.
💡You don’t necessarily need to fine-tune from scratch again for every new base model version. Instead, fine-tune once and add the diff vector to updated versions! ♻️♻️♻️. This can also offer a stronger and more computationally efficient starting point when further training is feasible.
📰: tinyurl.com/finetuning-trans…
More 👇


Thinh retweeted

A few weeks ago, I started a new job at @OpenAI. I wrote a document about my interview process and recommendations for anyone on the job market for AI research positions. I hope it's helpful!
docs.google.com/document/d/1…
Thinh retweeted

1/n I’m thrilled to share that our @OpenAI reasoning system scored high enough to achieve gold 🥇🥇 in one of the world’s top programming competitions - the 2025 International Olympiad in Informatics (IOI) - placing first among AI participants! 👨💻👨💻

Thinh retweeted

Most search models need the cloud.
II-Search-4B doesn’t.
4B model tuned for reasoning with search tools, built for local use.
Performance of models 10x its size.
Search that is small, smart, and open.
🥳Congrats @ii_posts for an impressive result on SEAL-0, a challenging benchmark for search-augmented LLMs.
🤩Looking forward to the evaluation standards it shapes in this field.
📚Read more: arxiv.org/abs/2506.01062


Thinh retweeted

. @EMostaque came back on the show to chat about:
--how we can't compete against AI agents
--his solution for a POSITIVE AI world
--Why UBI won't work but UBAI might..
--we need to be focused on incentivizing the right outcomes
-- Nations need sovereign AI stacks or they'll be left behind by the mega-models