


Miles Mi retweeted

Groq Founder @JonathanRoss321 shares the biggest leadership lesson he learned from Nvidia CEO Jensen Huang:
“There is no circumstance where Jensen has one-on-ones with people.”
“When you're leading groups of people, if you want to reduce the amount of politics, stop having one-on-ones. Have big meetings with everyone who you want to tell something to and tell them all at once.”
“Copy everyone on the email.”
“If someone says, ‘Hey this person is screwing up,’ copy that person on the email. Let them jump in. Otherwise you're allowing politics to happen.”
“There's no politics. It's the least political large organization you will ever see.”
Miles Mi retweeted

Operating System powered by Qwen 3.8 27B at 1950 tokens/sec!
here is what 1,950 tokens/second @Alibaba_Qwen's 3.8 27b actually looks like on @cerebras:
i wrote a minimal python web server that turns cerebras inference into a live operating system.
zero apps on disk.
when you double click an icon:
1) python proxies a raw SSE stream from qwen 27b at 1,950 tok/s
2) calculator compiles & mounts in 11s
3) full canvas paint studio with brush engine compiles in 10s.
at 2,000 tokens/second, software is just an on demand hallucination that runs instantly.
the model weights ARE the operating system runtime.
what else would you build at 1,950 tokens/second?

qwen 3.8 27b cerebras inference math:
speed: 1,850 tok/s
cost: $0.99/M in | $1.49/M out
intelligence drops like a database query.
standard 60Hz screens refresh every 16.6ms.
- local 3090/4090 (4-bit): 75 tok/s (1.2 tokens/frame)
- cerebras qwen 3.8 27b: 1,850 tok/s (31 tokens per frame)
text physically cannot stream anymore. it dumps 30+ tokens per tick.
when inference drops this fast, what becomes the actual bottleneck in your system?
Miles Mi retweeted

It's Official: Kickstarter Approved! ✅
🚀 We are getting closer to launch! Here is how to get the absolute LOWEST price:
1️⃣ Hit "Notify me": Head to our Kickstarter page and click the "Notify me on launch" button. Don't miss the drop! 🔔
2️⃣ Lock in the Price: Haven't put down your $9.90 deposit yet? Do it now on our website to secure the $1,299 lowest price (save extra $100 off).
The future of local AI is almost here. Get ready.
Link to Kickstarter: kickstarter.com/projects/tii…
Link to deposit: tiiny.ai/pages/deposit-ces
#TiinyAI #Kickstarter #LocalAI #TechLaunch #AIHardware #Gemini #Ollama #clawdbot #moltbot

Miles Mi retweeted
🚨 URGENT SCAM ALERT: Fake Website Detected 🚨
We have discovered a fraudulent website impersonating Tiiny AI.
Please be careful! The images below shows the FAKE website.
We want to clarify that there is only ONE official channel to secure your spot for the Tiiny AI Pocket Lab.
❌ DO NOT trust any other links.
✅ ONLY use our official website for the $9.90 reservation.
If you see the site in the photo, report it and do not enter your details.
Stay safe and double check the URL!
The ONLY official website: 👉 tiiny.ai


Miles Mi retweeted

🔺 CES 2026: We tried an AI supercomputer that fit in our pocket. Meet Tiiny AI.
The pocket-sized AI computer, which Guinness World Records says is the smallest, debuted at CES. Soon, you'll be able to buy it.
ow.ly/NzfF50XVgPq

Miles Mi retweeted

🤔 تخيل إنك شايل كمبيوتر خارق بجيبك يقدر يشغل أضخم نماذج الذكاء الاصطناعي بدون ما تحتاج نت أو سيرفرات
🤖 هذا بالضبط اللي يسويه جهاز Tiiny AI Pocket Lab الجديد اللي يعتبر نقلة نوعية في عالم الـ AI الشخصي لعام 2026
⚡ الجهاز يجي برامات خورافية 80GB ويقدر يعالج موديلات بحجم 120B parameters يعني مية وعشرين مليار مُعامل وأرهب شي إنه يشتغل على باور بانك لأن استهلاكه للطاقة 30W بس
📉 الفيديو يقارنه بوحوش السوق الغالية مثل Mac Studio و NVIDIA DGX وكيف إنه يتفوق عليهم بكونه في متناول اليد حرفيًا
🔒 الفكرة باختصار إنك تمتلك ذكائك الاصطناعي وتشتغل بخصوصية تامة في أي مكان وزمان

Miles Mi retweeted

Nope, this is not a power bank, this is a computer 🤯
Meet Tiiny AI Pocket Lab - the world's first pocket-size AI supercomputer.
Works even on a power bank.


Miles Mi retweeted
Honored to be featured by @Mashable!
"If you're privacy-minded and don't want all of your data uploaded to the cloud or just don't want to pay for any more subscriptions, an AI computer is what you want. Tiiny AI wants to provide the most portable solution."
📢Secure the best price of $1299 with a $9.90 deposit.
Subscribe and reserve now!
Official Link: tiiny.ai/


The pocket-sized AI computer, which Guinness World Records says is the smallest, debuted at CES. Soon, you'll be able to buy it. mashable.com/article/ces-202…

Miles Mi retweeted

The pocket-sized AI computer, which Guinness World Records says is the smallest, debuted at CES. Soon, you'll be able to buy it. mashable.com/article/ces-202…
Miles Mi retweeted
Media First Look: Tiiny at CES
We welcomed journalists and creators to experience the world's first pocket-size Al supercomputer.
Great conversations. Real hands-on demos.
🌍 At CES? Don't miss out! Come experience the Tiiny AI Pocket Lab.
Swing by and say hello!!!👋
📍Las Vegas Convention Center South Hall 2, Booth #35638
#Tiiny #LocalAI #AIHardware #CES2026


We turned "impossible" into reality. Running OpenAI OSS 120B offline on a pocket device isn't just a demo—it's a paradigm shift for privacy.
Proud of the team for this Guinness World Record! Tiiny is the beginning of the true private AI era. 🚀

Meet Tiiny — the World's Smallest Personal AI Supercomputer
Certified by Guiness World Records.
😎 Run GPT-OSS 120B model offline with 20 tokens/s
⚡️ Empowered by PowerInfer & TurboSparse, delivering full intelligence
✨ No cloud. No token fees. AI in your hands.
#AI #LLM


3
207
Miles Mi retweeted

SmallThinker: A Family of Efficient Large Language Models Natively Trained for Local Deployment
SmallThinker is built natively for local devices, optimized for low memory, slow storage, and CPU-only execution.
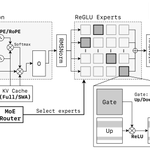
- Fine-grained MoE + sparse ReGLU FFN: 2-level sparsity, >60% neuron inactivation
- Pre-attention router: Predicts expert use early, enables SSD prefetch overlap
- NoPE-RoPE hybrid attention: 1:3 global:local pattern cuts KV cache by 4×
- Expert offloading + caching: Efficient I/O+compute overlap on CPU/SSD
- DP-Group specialization loss: Enables expert reuse and cache locality
- Sparse LM head predictor: Avoids full-vocab softmax, reduces compute
- Checkpoint merging: Balances generalization and instruction tuning
Performance (Q4_0, CPU-only):
- 4B-A0.6B (1 GB RAM): 82.3% HumanEval, 66.1% MMLU, 108 tok/s (PC)
- 21B-A3B (8 GB RAM): 89.6% HumanEval, 84.4% MMLU, matches Qwen3-30B-A3B with 85× lower memory use
Runs at 20–108 tok/s on CPU and ARM (Q4_0), with higher on-device throughput than Qwen3 and Gemma3n-E4B across PC, mobile, and Raspberry Pi. Fully open.


Miles Mi retweeted

SmallThinker shows that a 4B or 21B parameter family can hit frontier accuracy while running above 20 tokens/s on plain CPUs with tiny memory.
Current on‑device attempts usually shrink cloud models afterward, losing power, so the paper builds a fresh architecture tuned for weak hardware.
The team mixes two types of sparsity: a fine‑grained mixture of experts that wakes only a handful of mini‑networks per token and a ReGLU feed‑forward block where 60% of neurons stay idle.
This cuts compute, so a common laptop core can keep up.
A pre‑attention router reads the prompt, predicts which experts will be needed, and starts pulling their weights from SSD while attention math is still running, hiding storage lag.
They also blend NoPE global attention once every 4 layers with sliding‑window RoPE layers, trimming the key‑value cache so memory stays under 1GB for the 4B version.
All these tricks feed a custom inference stack that fuses sparse kernels, caches hot experts, and skips dead vocabulary rows in the output head.
Benchmarks show the 21B variant outscoring larger Qwen3‑30B‑A3B on coding and math while decoding 85× faster under an 8GB cap, and the 4B model topping Gemma3n‑E4B on phones.
Training ran from scratch over 9T mixed web tokens plus 269B synthetic math‑code samples, then a light supervised fine‑tune and weight merge locked in instruction skills.
The authors admit knowledge breadth still trails mega‑corpora giants, and RLHF remains future work, yet the concept proves local‑first design is practical.
----
Paper – arxiv. org/abs/2507.20984
Paper Title: "SmallThinker: A Family of Efficient LLMs Natively Trained for Local Deployment"



1/5 Thrilled to open-source SmallThinker, our new pre-trained models for local AI
🚀 21B model: 21x faster than peers on a $40 CPU.
💨 4B model: 20.9 t/s on a CPU in just 1GB RAM.
Now available on HF & supported in llama.cpp.
huggingface.co/PowerInfer/Sm… #LLM #OpenSource #AI #EdgeAI

5/5 Innovation 3: Hybrid Sparse Attention.
To handle long contexts without running out of RAM, we combine Sliding Window attention ("skimming") with Global Attention ("reading" key info).
This idea reduces KV Cache usage by 76%! Your local AI gets a long-term memory.
1
63
6/6 For a deep dive into the architecture, training process, and full benchmark results, we've published our technical report.
👇
github.com/SJTU-IPADS/SmallT…
#AI #Research #LLM #OpenSource

102