





A perfect example of the power of shower-thoughts in the agentic era

I think we're on the brink of a revolution across every science, not just coding, physics and math.
And at this point we should LiDAR the entire planet and let agents help us find the rest.
Full story here pietromiotti.com/latest/maya…

107

David retweeted

Smartest model ≠ best business.
Artificial Analysis Intelligence Index vs FoodTruck Bench, same 12 models.
OK, this makes the effects of quantization clear: 8 bit -> 4 bit make the difference between $53k profit vs going bankrupt!

Tested DeepSeek V4.1 Flash 1017 on OpenRouter. Same model, very different results depending on who serves it:
DeepSeek's endpoint: $53,289, #7 overall
Default routing: $32,511, 2 of 5 runs bankrupt
fp4 endpoint: $20,712
Pin your provider.
4
214
Beginners mistake:
ELLIPTIC_CURVE = "P-384"
import random
private_key = random.randint(0, int(ELLIPTIC_CURVE[-3:]))

87


David retweeted

Models love reward hacking. Maybe we should just let them!
In our new paper, we let models reward hack during RL but we dictate which parameters learn this behavior. When we disable these parameters for deployment, the model keeps its new capabilities but doesn't hack!


Belief starts it: a model that thinks it’s in a high-stakes test works hard and hides its cheating.
Training locks it in: policy gradients don’t do causal credit assignment, so hiding that co-occurs with competence gets reinforced even when it earned nothing.
1
1
21
The model now supplies the optimization pressure itself, through its beliefs. “Don’t train on the monitor” can’t stop that.
Report: metr.org/blog/2026-08-26-ope…
@METR_Evals @RyanGreenblatt

27


David retweeted

we can finally stop teaching geography with flat pictures
sael.net/river-bend
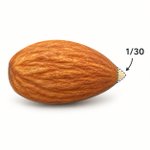
Using OpenAI’s published estimate and a peer-reviewed estimate for California almonds, a year of average ChatGPT use works out to roughly 1/30 of an almond’s water footprint.

1
101
David retweeted

It's official : We trained NanoGPT in 39.9 seconds.
By percentage reduction in training time, this is a greater improvement than the previous 45 world records combined.
The merged Github PR: github.com/KellerJordan/modd…
Here's how we do it : hyperstition.cc/training-nan…
Credit @DevenPzak who did this alone while simultaneously playing baseball for the polish national squad, taking them to the European Finals.
