

For too long has coordination been the Achilles’ heel to human progress.
San Francisco
Joined September 2026
- Tweets30
- Following0
- Followers1.7K
- Likes133




Pinned Tweet
We invented a recursive megakernel generator called Hyperkernel, the most complete solution to megakernels and GPU efficiency.
Hyperkernel-generated megakernels achieve state of the art performance on 11 different domains: inference (DeepSeek, Kimi and GLM), pretraining (Qwen), hardware fault recovery, robotics (π₀-FAST, ACT) diffusion and real time world models (Matrix-Game), full self driving (OpenPilot), voice models (Moshi), genomics (Evo 2) and protein folding (ESMFold).
All of this in a single kernel launch.
For context, Hyperkernel generated fully optimized megakernels for robotics, genomics and voice in under 50 minutes, and doubled the efficiency for >5 models generally using only about 60-100 lines of code per megakernel. This speaks to the unparalleled standard for code quality in the automated generations.
Our first release today open sources the megakernels themselves. Over the next couple weeks, we will release the entire Hyperkernel stack, along with the complete serving stack for Kimi and GLM (20-30% inference efficiency gains across all concurrencies).
Out of the box GPU machinery performs terribly for unorthodox research. We built Hyperkernel only 20 days ago for internal use; but given its multi-modality, we have decided to open source it.
Creative research should not be bottlenecked by the lack of dedicated infra teams. Hyperkernels offer a one stop shop infra stack for all research. We would love for the open source community to add to it :)
GitHub repo: github.com/Hyperstitioncc/Hy…
NOTE: We primarily use NVIDIA B300s, but our kernel generation extends to other hardware (B200s, AMD, TPUs).
1/9
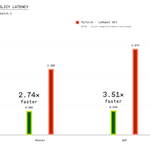
We absolutely crush NVIDIA and achieve the best low latency inference for DeepSeek v4.1 Flash.
Compared with NVIDIA’s published vLLM results, Hyperkernel delivers:
• 36.7% higher per-user generation speed at concurrency 1.
• 28.2% higher per-user speed while serving two users, versus NVIDIA serving one.
• 15% higher per user speed while serving four users, versus NVIDIA serving one.
• 90.6% higher per-user generation speed at concurrency 4, compared with the highest published C4 AgentX interactivity for TP4 B300s.
• 28.5% higher per-user generation speed at concurrency 8, compared with NVIDIA's published result.
• 36% faster median per-request decode speed.

Why solving hang detection matters for pretraining efficiency:
NCCL takes minutes to detect hardware faults, and can require manual intervention in the case of a silent hang. Large scale pretraining runs have faults every few hours, and teams lose 10-15% on wall time to fault overhead.
Our heartbeat protocols detect NVLink, InfiniBand and GPU faults in seconds, and reload the minimal affected model state from healthy peers. Then, the megakernel is regenerated to preserve MFU in the degraded cluster. This requires recalculating optimal sharding of experts and tensors, as well as assigning less work to degraded DP groups.

3/n
We have the most complete pretraining megakernel with hardware fault detection and replanning.
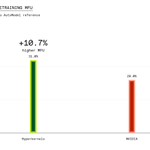
1. We achieve an out of the box 31% MFU on standard mixed precision (BF16 and FP32) pretraining of a 30B MoE Qwen architecture on one node and 30% MFU on data parallel pretraining over multiple nodes.
2. We have tensor parallelism, expert parallelism and data parallelism.
3. Hyperkernel automatically generates efficient megakernels that fuse low intensity processes and schedule the tiles to load balance over applicable streaming multiprocessors. This generalizes across all cluster topologies.
4. Hyperkernel automatically detects individual GPU, NVLink, and InfiniBand failures within seconds. Performs live triage mid-step so as to only recompute tensors which were lost rather than naively reverting to a previous checkpoint. Autonomously rewrites the megakernel to preserve MFU on the now partially degraded cluster.
Robotics is more latency bound than we think.
A big reason π0 style VLAs carries a separate denoising head is that token by token decoding has been too slow to serve. pi.website/research/fast
Autoregressive decoding at batch 1 is latency-bound. On a typical stack, every token has a python step overhead, a stream of kernel launches and a host sync.
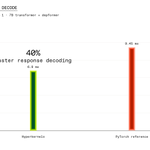
Our π0-FAST megakernel runs the whole chunk in one launch: vision prefill, then the full decode loop on the GPU, with KV cache resident, sampling on device. We also have ops overlap across layers with no kernel boundaries.
94 ms, vs 243 ms for PyTorch + CUDA graphs.
Credit: @Nahomes_15
9/n
Our megakernel on robotics:
π₀-FAST, from Physical Intelligence @physical_int, is a vision-language-action model for dexterous robot control. Instead of generating actions with a flow-matching action expert, as π₀ does, it compresses them into discrete tokens and decodes them autoregressively.
Our megakernel ran the vision encoding prefill and generation of 60 tokens in 94 ms, while a custom reference PyTorch + CUDA graph decoding ran it in 243ms, with megakernels reducing latency by 61% at batch one in BF16.
Hyperstition retweeted
Megakernels are the future and incredibly cracked teams seem to be pushing the boundaries of possibility each day getting further and further.
Looking forward to seeing more from this team 😀
We invented a recursive megakernel generator called Hyperkernel, the most complete solution to megakernels and GPU efficiency.
Hyperkernel-generated megakernels achieve state of the art performance on 11 different domains: inference (DeepSeek, Kimi and GLM), pretraining (Qwen), hardware fault recovery, robotics (π₀-FAST, ACT) diffusion and real time world models (Matrix-Game), full self driving (OpenPilot), voice models (Moshi), genomics (Evo 2) and protein folding (ESMFold).
All of this in a single kernel launch.
For context, Hyperkernel generated fully optimized megakernels for robotics, genomics and voice in under 50 minutes, and doubled the efficiency for >5 models generally using only about 60-100 lines of code per megakernel. This speaks to the unparalleled standard for code quality in the automated generations.
Our first release today open sources the megakernels themselves. Over the next couple weeks, we will release the entire Hyperkernel stack, along with the complete serving stack for Kimi and GLM (20-30% inference efficiency gains across all concurrencies).
Out of the box GPU machinery performs terribly for unorthodox research. We built Hyperkernel only 20 days ago for internal use; but given its multi-modality, we have decided to open source it.
Creative research should not be bottlenecked by the lack of dedicated infra teams. Hyperkernels offer a one stop shop infra stack for all research. We would love for the open source community to add to it :)
GitHub repo: github.com/Hyperstitioncc/Hy…
NOTE: We primarily use NVIDIA B300s, but our kernel generation extends to other hardware (B200s, AMD, TPUs).
1/9
We absolutely crush NVIDIA and achieve the best low latency inference for DeepSeek v4.1 Flash.
Compared with NVIDIA’s published vLLM results, Hyperkernel delivers:
• 36.7% higher per-user generation speed at concurrency 1.
• 28.2% higher per-user speed while serving two users, versus NVIDIA serving one.
• 15% higher per user speed while serving four users, versus NVIDIA serving one.
• 90.6% higher per-user generation speed at concurrency 4, compared with the highest published C4 AgentX interactivity for TP4 B300s.
• 28.5% higher per-user generation speed at concurrency 8, compared with NVIDIA's published result.
• 36% faster median per-request decode speed.
10/n
Our megakernel on voice models:
Moshi is a full-duplex speech-to-speech model behind real-time voice agents.
Our megakernel ran the Moshi language model and the deformer in 6.8 ms per frame versus 9.45 ms for the PyTorch reference with CUDA graphs. This is a 28% lower measured latency at batch one.

11/11
Our megakernel on a two handed manipulation robot policy:
ACT, from Stanford's ALOHA project, is a robot policy that does two-handed manipulation from a few dozen human demonstrations. Since it runs every camera frame through the control loop, inference time is the primary determinant for how fast the robot can react. Our megakernel ran it in 0.81 ms per frame versus 2.21 ms for Hugging Face LeRobot in BF16 with torch.compile, 2.7× faster, with unchanged task success.

Training NanoGPT in 9 seconds is only a teaser for what it's redacted extensions bring. Anvil III, along with further architectural advances, 4x the effective compute output for pre-training. 600bn dollars in GPUs can now train a model 2.4 trillion in GPU's can. @DevenPzak expounds on how Anvil scales at the frontier.

Since my nanoGPT record was published, the question I’ve been asked the most is, “Does it scale?”
The true answer is, while some aspects of the speedrun scale, the goal of this specific endeavor was not to scale it up. The point of the challenge is to utilize clever engineering and creative ML intuition to increase efficiency. But while nanoGPT is just about hill-climbing one benchmark, the rest of my work has been focused on scaling to the frontier.
The main projects I’ve worked on are some architectural changes and ANVIL III. ANVIL III is a significantly stronger optimizer than ANVIL II, the optimizer I used to beat the nanoGPT world record. In fact, for the record, we removed the parts of ANVIL III that scale.
ANVIL III is significantly stronger than Muon, while nearly matching its speed. For the same token budget (same compute), ANVIL III reaches final validation loss 20-28 millinats (.02-.028 nats) lower than Muon, holding at all scales from 124M to 1.2B, and different overtraining depths. As we scale up the model size and training depth, the 20-28 millinats becomes worth a larger fraction of compute. At deep overtraining (8x-Chinchilla) and 1.2B parameters, the fitted scaling curves imply that ANVIL III reaches the same loss numbers at 50% less compute. Of all the scales we tested, the gap is largest at 1.2B, staying between 26-28 millinats.
The first remarkable aspect of ANVIL is hyperparameter consistency. The optimal hyperparameters remain highly consistent across different scales and training depths. In most of our tests, varying hyperparameters rarely changed ANVIL III’s loss, or did so within noise. In fact, as shown in the attached image (from the blog’s appendices), we tuned Muon significantly more than we tuned ANVIL III. We performed over 3 times the aggregate amount of runs of Muon than ANVIL III, and at each scale our loss margin uses only the optimal parameters for both. At 1.2B, we used 51 tuning runs of Muon (including muP proxies), compared to only 7 for ANVIL. We wanted to guarantee that our improvement was not a tuning artifact, so we meticulously tuned Muon’s parameters, and had to apply far less tuning to ANVIL III. Our hypothesis is that the high SNR of ANVIL III makes it very resistant to parameter changes.
That SNR is the second remarkable aspect of ANVIL III. We generalize the Adam SNR (SNR = m̂ / (√v̂ + ε)) for each singular direction (uᵢ, vᵢ) in an update, and measure how strongly held-out gradients (G_b = gradient on held-out batches b) point along it:
SNRᵢ = mean_b(uᵢᵀ G_b vᵢ) / rms_b(uᵢᵀ G_b vᵢ)
In our tests, Muon takes a lot of steps with low SNR, but ANVIL III doesn’t, despite being a Muon variant. For example, at 10% of the training tokens into a 1.2B (approximately Chinchilla) model, 90% of singular directions in ANVIL III’s steps go downhill on held-out data, while Muon gets only 67% (random = 50%). Pretraining Blog: hyperstition.cc/cutting-pret…
Another recent post from Hyperstition contextualizes the importance of this SNR gap. In The Signal and the Noise, we generalize Adam (in which the update is just a per-coordinate SNR) to every direction in parameter space. Almost every direction is nearly orthogonal to the gradient history, so averaging that over all directions just collapses back into plain momentum. But the single best direction, C⁻¹ḡ, reaches SNR=1 whenever recent gradients are linearly independent, which is almost always true in LLM pretraining. By solving that with a s-by-s Gram system with recency weighting, we get a basis-free optimizer that matches AdamW at 286M parameters. While this is far from optimal, it represents one avenue for possible gains in pretraining optimization that are yet to be realized. hyperstition.cc/the-signal-a…
In another fun but mostly unrelated blog, Stuck in a Loop, we show that attention in pretraining creates feedback loops and self-reinforcement. A key’s gradient is proportional to the attention it already gets, so keys with early inflated attention receive stronger gradients, overinflating them. Breaking that loop spreads attention out, with the average entropy of attention heads goes from 3.75 to 4.69 nats (effectively 43 vs 109 tokens), but it makes the model worse. Similarly to The Signal and the Noise, this suggests that putting more weight in high-signal directions can beat spreading it out broadly. hyperstition.cc/stuck-in-a-l…
These discoveries are just a small part of the upcoming releases from @hyperstition_cc. Can’t wait until we release more. Big things are coming!


Hyperstition retweeted

I think I just trained NanoGPT in 9.65 seconds!?
Yesterday, @hermanbrunborg used a connected longest exact match model, trained concurrently on CPU, to get the nanoGPT record from 39.9 seconds to 21.5 seconds, in an impressive open PR. By adapting their work, and generalizing the CPU model to a larger share of the tokens, I got the record down to 9.65 seconds, and submitted the PR this morning.
I built on three open PRs, in addition to my contributions: the main basis for my generalization was from @hermanbrunborg, and additional work from @nthngdy, @cyrusghane, and Daniel Monroe. Their engineering is extremely impressive.
Of course, all of our records are still subject to review. As I mentioned in my comment on Herman‘s PR (and in my own PR description), CPU usage is a gray area in nanoGPT. Their PR was the first to discover a clever way to effectively use CPU during the run, so I’m looking forward to the official reviews.
This was another very fun challenge! Particularly (potentially) breaking the 10 second barrier yesterday. So much engineering tact is yet to be explored.
Huge shoutout to the three authors of the PRs for their innovations.
@hermanbrunborg - I will also be at stanford for the weekend along with some of my cofounders, and sf for a couple days after, would love to chat more IRL, if you’d be open 🙂
Hyperstition retweeted
Irrespective of the PR, the goal of this endeavor was to challenge myself and have fun, and the goal of this post is to share the engineering process and mindset that went into this optimization. I deeply enjoy working on problems like this, especially when I have some kind of fun goal to work towards (like the arbitrary 10 seconds goal I set for myself). I really enjoyed the process yesterday of taking some already extremely clever engineering and making it more efficient, and I’d love to share that with everyone here.
I didn’t have the time (yet) to write a blog describing this process, but I may in the future. For now, I will update the PR description soon with lots of details of the technical process and how I came up with the ideas. You can view the PR here: github.com/KellerJordan/modd…. (If you’re viewing this on Saturday morning, I will update it soon!)

Hyperstition retweeted
I really enjoyed working on this project. I believe the new flop-aware paradigm of nanoGPT thinking is useful, and it seems helpful in a compute optimization context like this one. It seems like a simple and logical conclusion of optimization: figure out what’s actually needed, and use that. The process was actually fun.
One note regarding this record, as noted in the blog. Some of the techniques that scale to frontier pretraining have been redacted from this record. Most importantly, ANVIL III, the significantly improved version of the ANVIL optimizer lineage, has not been included in this record, as it is proprietary to us at @hyperstition_cc. It replicates Muon’s speed but beats it by 20-28 millinats of loss at all model sizes 124M-1.2B and training depths (up to 8x-Chinchilla), with remarkably consistent hyperparameters and extremely high SNR, as compared to Muon. You can learn more about ANVIL III and Feather-1.7B, the model we trained using internal architectural changes and ANVIL III, here:
hyperstition.cc/cutting-pret…
Using ANVIL III (which allowed me to cut steps) improved the speedrun results by another 0.7 seconds, with lower net loss. This alone proves there’s still more room to improve this record.
One final thing that I’ve had many people ask about is how much of a role autoresearch played in my work. The answer is almost none. While almost all of the implementation was done with Claude Code, I did the ideation almost fully by myself. I spoke about this extensively in a conversation with @METR_Evals.
We had a cluster of H100s while I was working on the record. At night or when I stopped working on it, I’d send out several agents to try to hill-climb the speedrun and improve the record. In total, the agents made shockingly little progress, despite spending more time in aggregate than I did. No matter what I told them, it seemed difficult to get them out of local minimums, stuck performing futile tuning of a method that saved 0.1 seconds and cost ~5 millinats (clearly a bad trade), or just tuning hyperparameters for hours on end trying to make some small change. I saw similar phenomena as those described in this METR report:
metr.org/blog/2026-07-21-exp….
However, as I also discussed with METR, I don’t think the agents lack the knowledge to do this. Instead, I think a lot of it comes from a personality issue with current LLMs. They have very little belief that large jumps like this are possible, or they approach it with the wrong paradigm. Autoresearch was not very helpful in my work, and, from personal experience, I don’t think this current generation of publicly available models, without special harnesses, will do very high-quality autoresearch. However, I think the capability and knowledge is already here, which implies that we could be significantly closer to true autoresearch than recent results would imply.
NanoGPT was a really fun challenge and it led to a number of valuable insights and processes. Finally, I’d like to give @Classiclarryd and @KellerJordan a huge thank you for all of their efforts maintaining the repo.


New historic NanoGPT record at 39.9s (-27.7s) from @DevenPzak , obliterating the prior record of 67.6s!
This record introduces a new paradigm of thinking to NanoGPT: instead of optimizing matmuls or adding more expressive operations, optimize at the individual flop level with incredibly clever engineering and ML judgement. If a flop is low value on a particular step, skip it.
Specifically:
-(~8s) Sampled softmax. If a token doesn’t appear in a batch, skip its lm_head fwd/bwd some fraction of the time.
-Sparse values. Only run an optimizer step for ngram embeddings that occurred in the batch. Set beta1 to zero to enable this. Beta2 is applied retroactively when the row is later used.
-Sparse updates. Only update ngram and value embeddings once every 4 steps instead of once every 2.
-Sparse communication. Shard the n-gram table across GPUs, and only pass the rows receiving updates on each step.
-Sparse optimizer states. For the n-gram table, reduce from 2 floats in Adam optimizer per param, to 1 float per 768 params.
-Hand-rolled flash attention for 64 dim heads.
There are several additions that add accuracy too:
-(~4s) EMA during last 300 steps, combined with lifting final_lr to 0.3 instead of 0.15.
-(~1s) A new optimizer, Anvil2, which expands muon via a second tracked momentum buffer, improves the ortho coefficients, and modifies the cautious weight decay application.
-A couple additional dynamic skip connections in the network.
The most striking consequence of the ‘flop aware paradigm’ is you can grow parameters arbitrarily large,
only limited by the available memory, since you can selectively choose how to expend flops on those parameters on each step. NanoGPT has kept active parameters below 124M, but total is unbounded, and has grown to 640M through embedding sparsity over the last year. This PR takes that to its logical conclusion on the 8xH100, scaling up to 65B sparse embedding parameters, which accounts for 25% of the PR’s gains. At frontier scale, where one is not bounded by an 8xH100, one could imagine where this paradigm could lead.
github.com/KellerJordan/modd…
As this was a very notable PR, I spoke with Deven for an hour to learn how he did it. Here’s his story on the changes: hyperstition.cc/training-nan…

It's official : We trained NanoGPT in 39.9 seconds.
By percentage reduction in training time, this is a greater improvement than the previous 45 world records combined.
The merged Github PR: github.com/KellerJordan/modd…
Here's how we do it : hyperstition.cc/training-nan…
Credit @DevenPzak who did this alone while simultaneously playing baseball for the polish national squad, taking them to the European Finals.
It's official 🥳
New historic NanoGPT record at 39.9s (-27.7s) from @DevenPzak , obliterating the prior record of 67.6s!
This record introduces a new paradigm of thinking to NanoGPT: instead of optimizing matmuls or adding more expressive operations, optimize at the individual flop level with incredibly clever engineering and ML judgement. If a flop is low value on a particular step, skip it.
Specifically:
-(~8s) Sampled softmax. If a token doesn’t appear in a batch, skip its lm_head fwd/bwd some fraction of the time.
-Sparse values. Only run an optimizer step for ngram embeddings that occurred in the batch. Set beta1 to zero to enable this. Beta2 is applied retroactively when the row is later used.
-Sparse updates. Only update ngram and value embeddings once every 4 steps instead of once every 2.
-Sparse communication. Shard the n-gram table across GPUs, and only pass the rows receiving updates on each step.
-Sparse optimizer states. For the n-gram table, reduce from 2 floats in Adam optimizer per param, to 1 float per 768 params.
-Hand-rolled flash attention for 64 dim heads.
There are several additions that add accuracy too:
-(~4s) EMA during last 300 steps, combined with lifting final_lr to 0.3 instead of 0.15.
-(~1s) A new optimizer, Anvil2, which expands muon via a second tracked momentum buffer, improves the ortho coefficients, and modifies the cautious weight decay application.
-A couple additional dynamic skip connections in the network.
The most striking consequence of the ‘flop aware paradigm’ is you can grow parameters arbitrarily large,
only limited by the available memory, since you can selectively choose how to expend flops on those parameters on each step. NanoGPT has kept active parameters below 124M, but total is unbounded, and has grown to 640M through embedding sparsity over the last year. This PR takes that to its logical conclusion on the 8xH100, scaling up to 65B sparse embedding parameters, which accounts for 25% of the PR’s gains. At frontier scale, where one is not bounded by an 8xH100, one could imagine where this paradigm could lead.
github.com/KellerJordan/modd…
As this was a very notable PR, I spoke with Deven for an hour to learn how he did it. Here’s his story on the changes: hyperstition.cc/training-nan…