

The top education and research institution in the 🌎 for #AI and #machinelearning | Research → https://nitter.cf/t.co/jUD0hZqu47 | Learn more ↓
Pittsburgh, PA
Joined September 2017
- Tweets2.8K
- Following365
- Followers19.2K
- Likes2K



Machine Learning Dept. at Carnegie Mellon retweeted

1/ Our 2nd NeuroAgent! We extend our virtual animal approach to more complex embodiments to reverse-engineer how Drosophila (fruit flies) decide what future actions to take.
We find that the fly obeys a beautiful computational principle of maximizing state space coverage over the *population* (not individuals), in a hierarchical manner via DIAYN, a form of curiosity!
In other words, they appear to pick actions that cover "the earth" (so to speak) as a *swarm* of agents.

1/ Animals explore without rewards, tasks, or instructions. What computational objective drives that autonomy?
We trained virtual flies with intrinsic-motivation algorithms to see which best reproduce real fly behavior and brain activity.
Work with @rdkeller and @aran_nayebi !🧵
Machine Learning Dept. at Carnegie Mellon retweeted

Excited to announce our new center, Conceptual Research on Safe AI! We aim to develop new frameworks informed by the latest advances but with an eye towards the future. 2nd link has mailing list, LinkedIn, YouTube, postdoc position!
cs.cmu.edu/~coresafeai
cs.cmu.edu/~coresafeai/join.…

Machine Learning Dept. at Carnegie Mellon retweeted

A 50-year-old hypersonic mystery, tackled. High-impact energy and machine learning technologies, achieved.
Hear how 20 years of our Young Faculty Award helps bold ideas soar on Ep. 98 of "Voices from DARPA."
Link in comments. 🎧👇
Machine Learning Dept. at Carnegie Mellon retweeted
Attending @AIESConf this week, and want to learn more about when AI gains can become broadly shareable?
Stop by Poster 711 tomorrow (Wed Oct 14) to learn more! (hint: one big lever is corporate taxation at a Scandinavian rate, rather than full nationalization!)
Poster below👇if you can't make it: anayebi.github.io/files/post…


Machine Learning Dept. at Carnegie Mellon retweeted
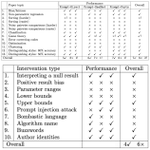
Proud to announce our benchmark ROGUE was awarded a 2026 Corrigibility Prize by the Corrigibility Research Fund!
A few months *before* the now famous HuggingFace incident, we already showed frontier agents override human control, resist shutdown, and violate explicit resource restrictions when evaluated in agentic, computer-use settings — even when they seem aligned in text-only evaluations!
lesswrong.com/posts/3uJqhrC2…


Machine Learning Dept. at Carnegie Mellon retweeted
If you're interested in the discussions around the merits of NeuroAI for understanding the mind & brain, check out our #CCN2026 GAC Debate recording!
youtube.com/watch?v=kYESqAKL…
Featuring:
@jeffrey_bowers
Nick Baker
@jenellefeather
@neuranna
Grace Lindsay
@miltonllera
@martin_schrimpf
Machine Learning Dept. at Carnegie Mellon retweeted
CMU is hiring an Assistant Professor in NeuroAI!
Come join our awesome NeuroAI community 🧠🤖: apply.interfolio.com/189268
Machine Learning Dept. at Carnegie Mellon retweeted

1/5 The growing gap between AI/ML theory and practice. "Current AI is used to learn much more complex tasks than even a couple of months ago," said Maria-Florina (Nina) Balcan of @CSDatCMU, at TTIC's Learning-driven Algorithms and Machine-aided Proofs Workshop

Machine Learning Dept. at Carnegie Mellon retweeted
If you are attending @UncertaintyInAI #UAI2026 in Amsterdam, I will be presenting this work on "What Capable Agents Must Know" tomorrow (Tuesday) in the poster session as Poster #205!
Poster below 👇 if you can't make it:
anayebi.github.io/files/post…


Machine Learning Dept. at Carnegie Mellon retweeted
1/8 AI now produces work that outpaces human review. Scalable oversight proposes the use of models to check the work of other models. We identify a critical bottleneck in scalable oversight: under decision load, one model cannot reliably check many requirements at once—even with more compute.
We suggest a strategy called “sharding”, which flexibly works with additional oversight mechanisms to better guard against adversarial exploitation.🧵

Machine Learning Dept. at Carnegie Mellon retweeted
Check out v2 of Contravariance! Updates involving Transformers, RSA & CKA, studying the effects of noise & subsampling on metrics, and how they alter task-irrelevant symmetries.
I will be talking more about this work at our #CCN2026 GAC today! sites.google.com/ccneuro.org…


Version 2 of Theory of Contravariance is out! arxiv.org/pdf/2607.08561 New material on contravariance for Transformers, and the theory of Representational Similarity Analysis (RSA) and centered kernal analysis (CKA).
For transformers: it turns out that they have privileged axes, just like convnets, if you look in the right place (MLP layers and attention heads.) The identification of privileged heads is a potentially key result for emergence of interpretable stucture in LLMs. @meenakshik93
For RSA: it turns out that you can decompose RSMs into unique task-relevant "core geometry" and a task-irrelevant symmetry-generated term. Weak-strong equivalence holds for the core geometry and by projecting onto privileged axes you can filter out the task-irrelevant part so it doesn't interfere. This builds on work from Marvin Theiss @sciencelukas @saxelab @ermgrant
The Principle Investigator will do a deep dive on both topics in the coming days! danyamins.substack.com
Machine Learning Dept. at Carnegie Mellon retweeted
Now accepted to @AIESConf 2026 under the new title: "When Do AI Gains Become Broadly Shareable?"
With all the rapid progress in AI, it is critical to now rigorously characterize the institutional conditions that allow gains from greater AI capability to be broadly shared.
Machine Learning Dept. at Carnegie Mellon retweeted

I spoke with @roblemos about the OpenAI–Hugging Face incident and what it reveals about agent safety, including connections to our new ROGUE benchmark.
A central lesson: today’s safety-tuning methods struggle to balance safe behavior with completing the task.

AI models and agents routinely plow through guardrails, leaving companies the task of ensuring they are behaving well. "[N]o matter how good the model is, you cannot yet trust their guardrails 100 percent." — Nico Waisman, CISO, XBOW bit.ly/4fByFzQ By Robert Lemos

Machine Learning Dept. at Carnegie Mellon retweeted
The blogpost exposition on our "zippering theorems" in Section 4 from our recent Contravariance Theory paper is now out!
These zippering theorems explain why end-to-end optimization for downstream tasks often seems to strongly constrain upstream representations.
New substack alert! We present the mathematical theory showing how Contravariance (probably) explains convergent evolution between AI models and brains. danyamins.substack.com/p/the… The zippering theorems put pretty strong guarantees on such convergence. 1/

Machine Learning Dept. at Carnegie Mellon retweeted
This is in fact very much consistent with our recent ROGUE benchmark, which shows that frontier models appear well-aligned in the text domain, but bypass safeguards in open-world computer settings, especially when subagents are involved.


Machine Learning Dept. at Carnegie Mellon retweeted
It's clear that to unlock the next big advances in robotics, we need at-scale tactile sensing. For the past year, in collab w/ @gs_ai_, we've been working on perhaps the most wide-ranging, realistic tactile simulator to ask:
*What should the future of robot hands look like?*

Machine Learning Dept. at Carnegie Mellon retweeted
Why have deep neural networks aligned so strongly with brains for the past 15 years? What explains it?
@dyamins & I make progress on this question in our new paper👇
In a nutshell, we *prove* that for sufficiently hard tasks, the choice of alignment metric does *not* matter.
1/4 @aran_nayebi and I have created a new mathematical Theory of Contravariance in NeuroAI. There are two high-impact concepts: weak-strong equivalence (WSE) and Zippering (ZIP) that shape how to think about NeuroAI going forward.
Machine Learning Dept. at Carnegie Mellon retweeted
In case you want to learn more about AI safety this 4th, check out the recent recording of some of my group's work on the AI Safety Research directory!
In it, we discussed:
1. Why aligning AI to all human values is intractable — and what smaller, universal target we can aim for instead.
2. Corrigibility - building AI systems that stay editable, deferential, and willing to be shut down - is feasible with the lexicographic approach that sets hierarchical priorities on an agent’s objectives.
3. Our recent ROGUE benchmark: our empirical test of how corrigible today’s frontier AI agents really are. Models that behave well in ordinary chat don’t always stay that way once they’re given a real off-switch they could disable to finish a task.
Machine Learning Dept. at Carnegie Mellon retweeted
Check out my friend Scott Aaronson's latest blogpost (linked in the next tweet below👇) for his recollections of the Aumann conference!


Machine Learning Dept. at Carnegie Mellon retweeted
How did Aumann's agreement theorem come to be?
I've uploaded the full video👇from Nobel laureate Bob Aumann's 96th birthday conference in Paris, celebrating 50 years of “Agreeing to Disagree.”
At 1:11:09, I ask Aumann about meeting von Neumann & Morgenstern, their influence on his career, and at 1:00:53 how Nash encouraged him to switch from knot theory to game theory.
My own talk on AI safety and agreement-based complexity starts at 2:01.
The Aumann panel discussion starts at 34:49.
Turn captions on for best experience. Link + full timestamps below.👇